簡単な答え: GPT-6 Sol is OpenAI’s complex coding and agentic workflows model. The official API lists $2.00 per 1M input tokens and $10.00 per 1M output tokens at Standard rates, with a 1.05M-token context window and 128K maximum output. GlobalGPT currently lists GPT-5.6 Sol and GPT-5.6 Luna rather than exact GPT-6 routes, so the platform naming must be checked separately from OpenAI’s API model ID.
OpenAI positions GPT-6 Sol for complex coding and agentic workflows. That phrase is provider positioning, not a measured quality score. This review translates the published specification into buying and architecture decisions, then records public reaction with attribution. We also ran a scoped compatibility-API test with the model ID, route, prompt set, raw output, and usage retained. The task results are shown below as one observed run, not as an official benchmark.
ひとくちレビュー
Sol is the model to examine when the work is genuinely complex, tool-heavy, or code-centric and the higher token bill is acceptable. The evidence here combines official documentation with a scoped compatibility-API observation, not a controlled benchmark, so the responsible verdict is fit, not a universal ranking.
The most useful distinction is not simply “smart” versus “fast.” It is workload shape. GPT-6 Sol has the same headline context and output ceilings as its sibling, but its positioning and price make a different operating point sensible. Compare the broader AI model selection guide そして コーディングに最適なAIモデル guide when the task spans more than one provider.
GPT-6 Sol at a glance
The table below follows the current official GPT-6 Sol model page. Context capacity is not the same thing as a recommended prompt size, and the maximum input is separate from the headline context window.
| フィールド | Official value |
|---|---|
| Official API ID | gpt-6-sol |
| Provider positioning | complex coding and agentic workflows |
| コンテキストウィンドウ | 1,050,000トークン |
| 最大入力 | 922,000 トークン |
| 最大出力 | 128,000トークン |
| 知識カットオフ | April 20, 2026 |
| 入力/出力 | Text + image input / text output |
| 推論努力 | none, low, medium, high, xhigh, max |
| Supported endpoints | Chat Completions, Responses, Batch |
Both sibling models support structured outputs, function calling, streaming, prompt caching, image input, file search, and web search in the documented feature set. The exact tool behavior still depends on endpoint, account, and request configuration; do not infer a successful tool run from a capability checkbox.
For family-level context, the GPT-6 Astra レビュー shows how a related GPT-6 article separates provider documentation, platform routes, and attributed reactions.
GPT-6 Sol pricing and the 272K rule
At Standard rates, the OpenAI pricing page lists $2.00 input, $0.20 cached input, $2.50 cache writes, and $10.00 output per 1M tokens. Cache writes are 1.25x uncached input. Batch and Flex are priced at 50% of Standard, Fast mode is 2x the applicable rate, and regional processing adds 10% where available.
| Rate category | Up to 272K input | Above 272K input |
|---|---|---|
| キャッシュされていない入力 | $2.00 / 1M | $4.00 / 1M |
| キャッシュされた入力 | $0.20 / 1M | $0.40 / 1M |
| キャッシュへの書き込み | $2.50 / 1M | $5.00 / 1M |
| 出力 | $10.00 / 1M | $15.00 / 1M |
The long-context column is calculated from OpenAI’s rule: above 272K input, input and cache rates double and output is multiplied by 1.5 for the full request. It is not a mixed-rate bill. For a practical budget baseline, 100K input plus 10K output costs about $0.30 before tools or regional uplift; a 300K input plus 20K output example costs about $1.50 at the long-context rates.
A large context window can be useful without being cheap to fill. Retrieval, chunk selection, cache reuse, and output caps matter more than the headline 1.05M number. See the GPT-6 Astra の価格内訳 for a related explanation of context thresholds and cache mechanics.
GPT-6 Sol API fit, tools, and limits
OpenAI recommends the Responses API for built-in tools and function calling. Chat Completions supports function calling only when 推論の努力 is set to なし. That is an implementation detail worth catching before migration: a request can be syntactically valid yet fail to match the tool behavior your current integration expects.
| 能力 | Supported or documented behavior |
|---|---|
| 回答 | Supported; built-in tools and function calling |
| Chat Completions | Supported; function calling only at reasoning_effort=none |
| バッチ | Supported; separate processing mode with 50% Standard token rates |
| Audio / realtime / video | Not supported on the model page |
| 画像入力 | Supported; output remains text |
| 最大入力 | 922,000 tokens; do not confuse this with the 1.05M context window |
The current rate-limit table lists the following Standard tiers. RPM means requests per minute, TPM means tokens per minute, and the queue value is the batch-token limit.
| ティア | RPM | TPM | バッチキュー |
|---|---|---|---|
| ティア1 | 500 | 500,000 | 1,500,000 |
| ティア2 | 5,000 | 1,000,000 | 3,000,000 |
| ティア3 | 5,000 | 2,000,000 | 100,000,000 |
| ティア4 | 10,000 | 4,000,000 | 200,000,000 |
| ティア5 | 15,000 | 40,000,000 | 15,000,000,000 |
Before production rollout, validate the exact tier, endpoint, streaming mode, and tool contract in your own account. The Codex usage limits guide is useful context for why a model’s published ceiling is not the same as an account’s live allowance.
What GPT-6 Sol’s specs imply
| Reader job | なぜこれが適しているのか | 確認すべき事項 |
|---|---|---|
| Complex coding | Configurable reasoning and tool support are aligned with multi-step code work. | Run repository-level tasks through the exact endpoint you will ship. |
| Agent loops | Responses tools, function calling, MCP, and hosted tools are documented capabilities. | Check tool permissions, retry behavior, and state handoff. |
| Long technical dossiers | 1.05M context and 922K maximum input leave room for large source sets. | Measure tokenization and the 272K price transition. |
| High-volume extraction | Possible, but the price sheet makes Luna the cheaper baseline. | Compare acceptance rate and total cost, not just output quality. |
This is a fit map, not a benchmark. Use the all-in-one AI models workflow guide when your real decision is how to switch models inside one repeatable process rather than which single model sounds strongest.
Hands-on API test: three matched tasks
We ran the same three small tasks through the Broly Anywhere compatibility API at https://anywhere.broly.ai/v1/chat/completions using model ID gpt-6-sol: a coding review, a long-context decision memo, and strict JSON extraction. These are useful workflow observations, not an official OpenAI benchmark or a universal ranking. The first two passes hit temporary HTTP 503 overload responses; after retrying, all three tasks completed at HTTP 200.
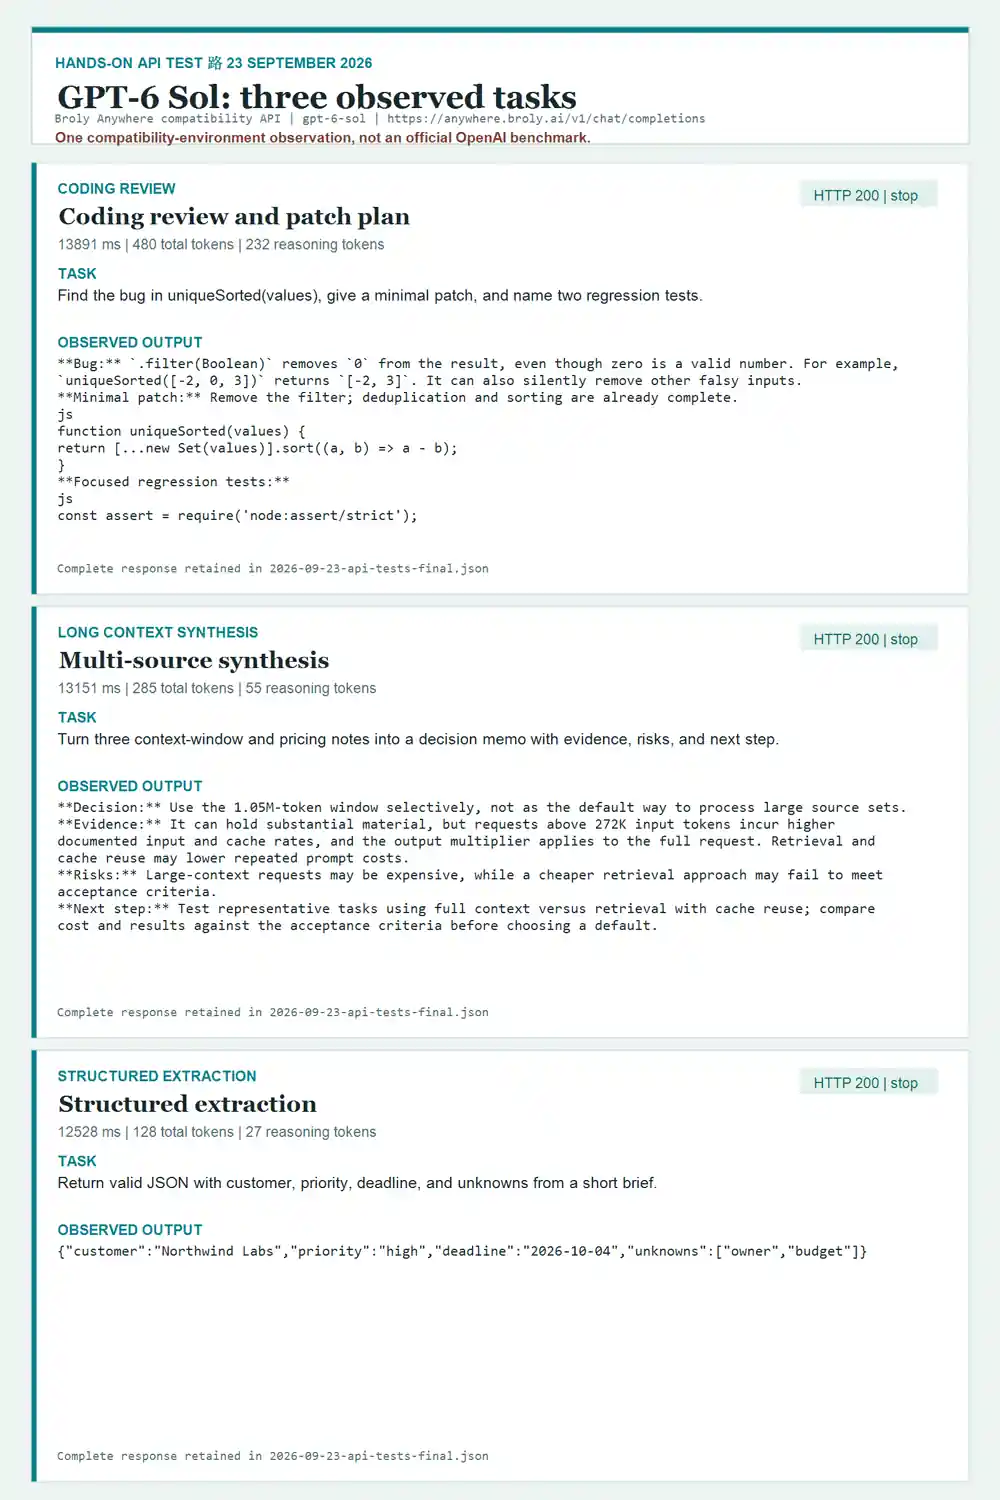
The complete JSON report keeps the full prompts, outputs, HTTP status, finish reason, latency, and usage fields. The cards below keep the same information editable in the WordPress source.
Coding review and patch plan
13891 ms · 480 total tokens · 232 reasoning tokens
Review this small JavaScript function as if it were part of a production repository. Identify the bug, explain the failure mode, and propose a minimal patch plus two focused regression tests. Function: function uniqueSorted(values) { return [...new Set(values)].sort((a, b) => a - b).filter(Boolean); }**Bug:** `.filter(Boolean)` removes `0` from the result, even though zero is a valid number. For example, `uniqueSorted([-2, 0, 3])` returns `[-2, 3]`. It can also silently remove other falsy inputs.
**Minimal patch:** Remove the filter; deduplication and sorting are already complete.
```js
function uniqueSorted(values) {
return [...new Set(values)].sort((a, b) => a - b);
}
```
**Focused regression tests:**
```js
const assert = require('node:assert/strict');
assert.deepStrictEqual(uniqueSorted([0]), [0]);
assert.deepStrictEqual(uniqueSorted([3, 0, -2, 0, 3]), [-2, 0, 3]);
```Multi-source synthesis
13151 ms · 285 total tokens · 55 reasoning tokens
Synthesize the following three notes into a concise decision memo with: decision, evidence, risks, and next step. Note A: A 1.05M-token context window can hold large source sets but does not make every request cheap. Note B: Above 272K input tokens, the documented input/cache rates increase and output is multiplied for the full request. Note C: Retrieval and cache reuse can reduce repeated prompt cost, but acceptance criteria still need testing.
**Decision:** Use the 1.05M-token window selectively, not as the default way to process large source sets.

**Evidence:** It can hold substantial material, but requests above 272K input tokens incur higher documented input and cache rates, and the output multiplier applies to the full request. Retrieval and cache reuse may lower repeated prompt costs.

**Risks:** Large-context requests may be expensive, while a cheaper retrieval approach may fail to meet acceptance criteria.

**Next step:** Test representative tasks using full context versus retrieval with cache reuse; compare cost and results against the acceptance criteria before choosing a default.
構造化抽出
12528 ms · 128 total tokens · 27 reasoning tokens
Extract the following fields from this brief and return valid JSON only with keys customer, priority, deadline, and unknowns. Brief: Customer: Northwind Labs. Priority: high. Deadline: 2026-10-04. The owner is not named and the budget is not confirmed.
{"customer":"Northwind Labs","priority":"high","deadline":"2026-10-04","unknowns":["owner","budget"]}In the coding task, GPT-6 Sol identified the falsy-value bug in filter(Boolean) and supplied a patch plus regression coverage; the completed run used 480 total tokens. In the long-context task, it kept the decision, evidence, risk, and next-step structure while carrying the 272K pricing caveat forward; the response used 285 total tokens. In the structured extraction task, it returned the requested customer, priority, deadline, and unknowns fields as JSON. Those are observed output shapes for this route, not evidence that one model is universally better.
What public reactions can and cannot tell you
The following sources are included as attributed public reaction, not as official documentation or controlled benchmark evidence. Their titles show what each creator chose to test or explain; they do not establish a market-wide result.
- Nate Herk | AI Automation: I Tested Opus 5.5 vs. GPT-6 Sol on 10 Real Use Cases. Treat the framing and any demonstration as that creator’s experience, not as a universal score.
- Arena AI: GPT-6 Sol | First impressions. Treat the framing and any demonstration as that creator’s experience, not as a universal score.
- Chase AI: GPT 6 Sol & Luna Are Here (And 50% CHEAPER!). Treat the framing and any demonstration as that creator’s experience, not as a universal score.
A separate naming issue matters here: several public videos use “GPT-6” and “GPT-5.6” interchangeably in titles. Keep the exact model ID visible when you reproduce a claim. The GPT-6 Astra と GPT-5.6 Sol の比較 is a useful example of why provider identity, platform label, and route should be recorded separately.
GlobalGPT access and the GPT-5.6 naming note
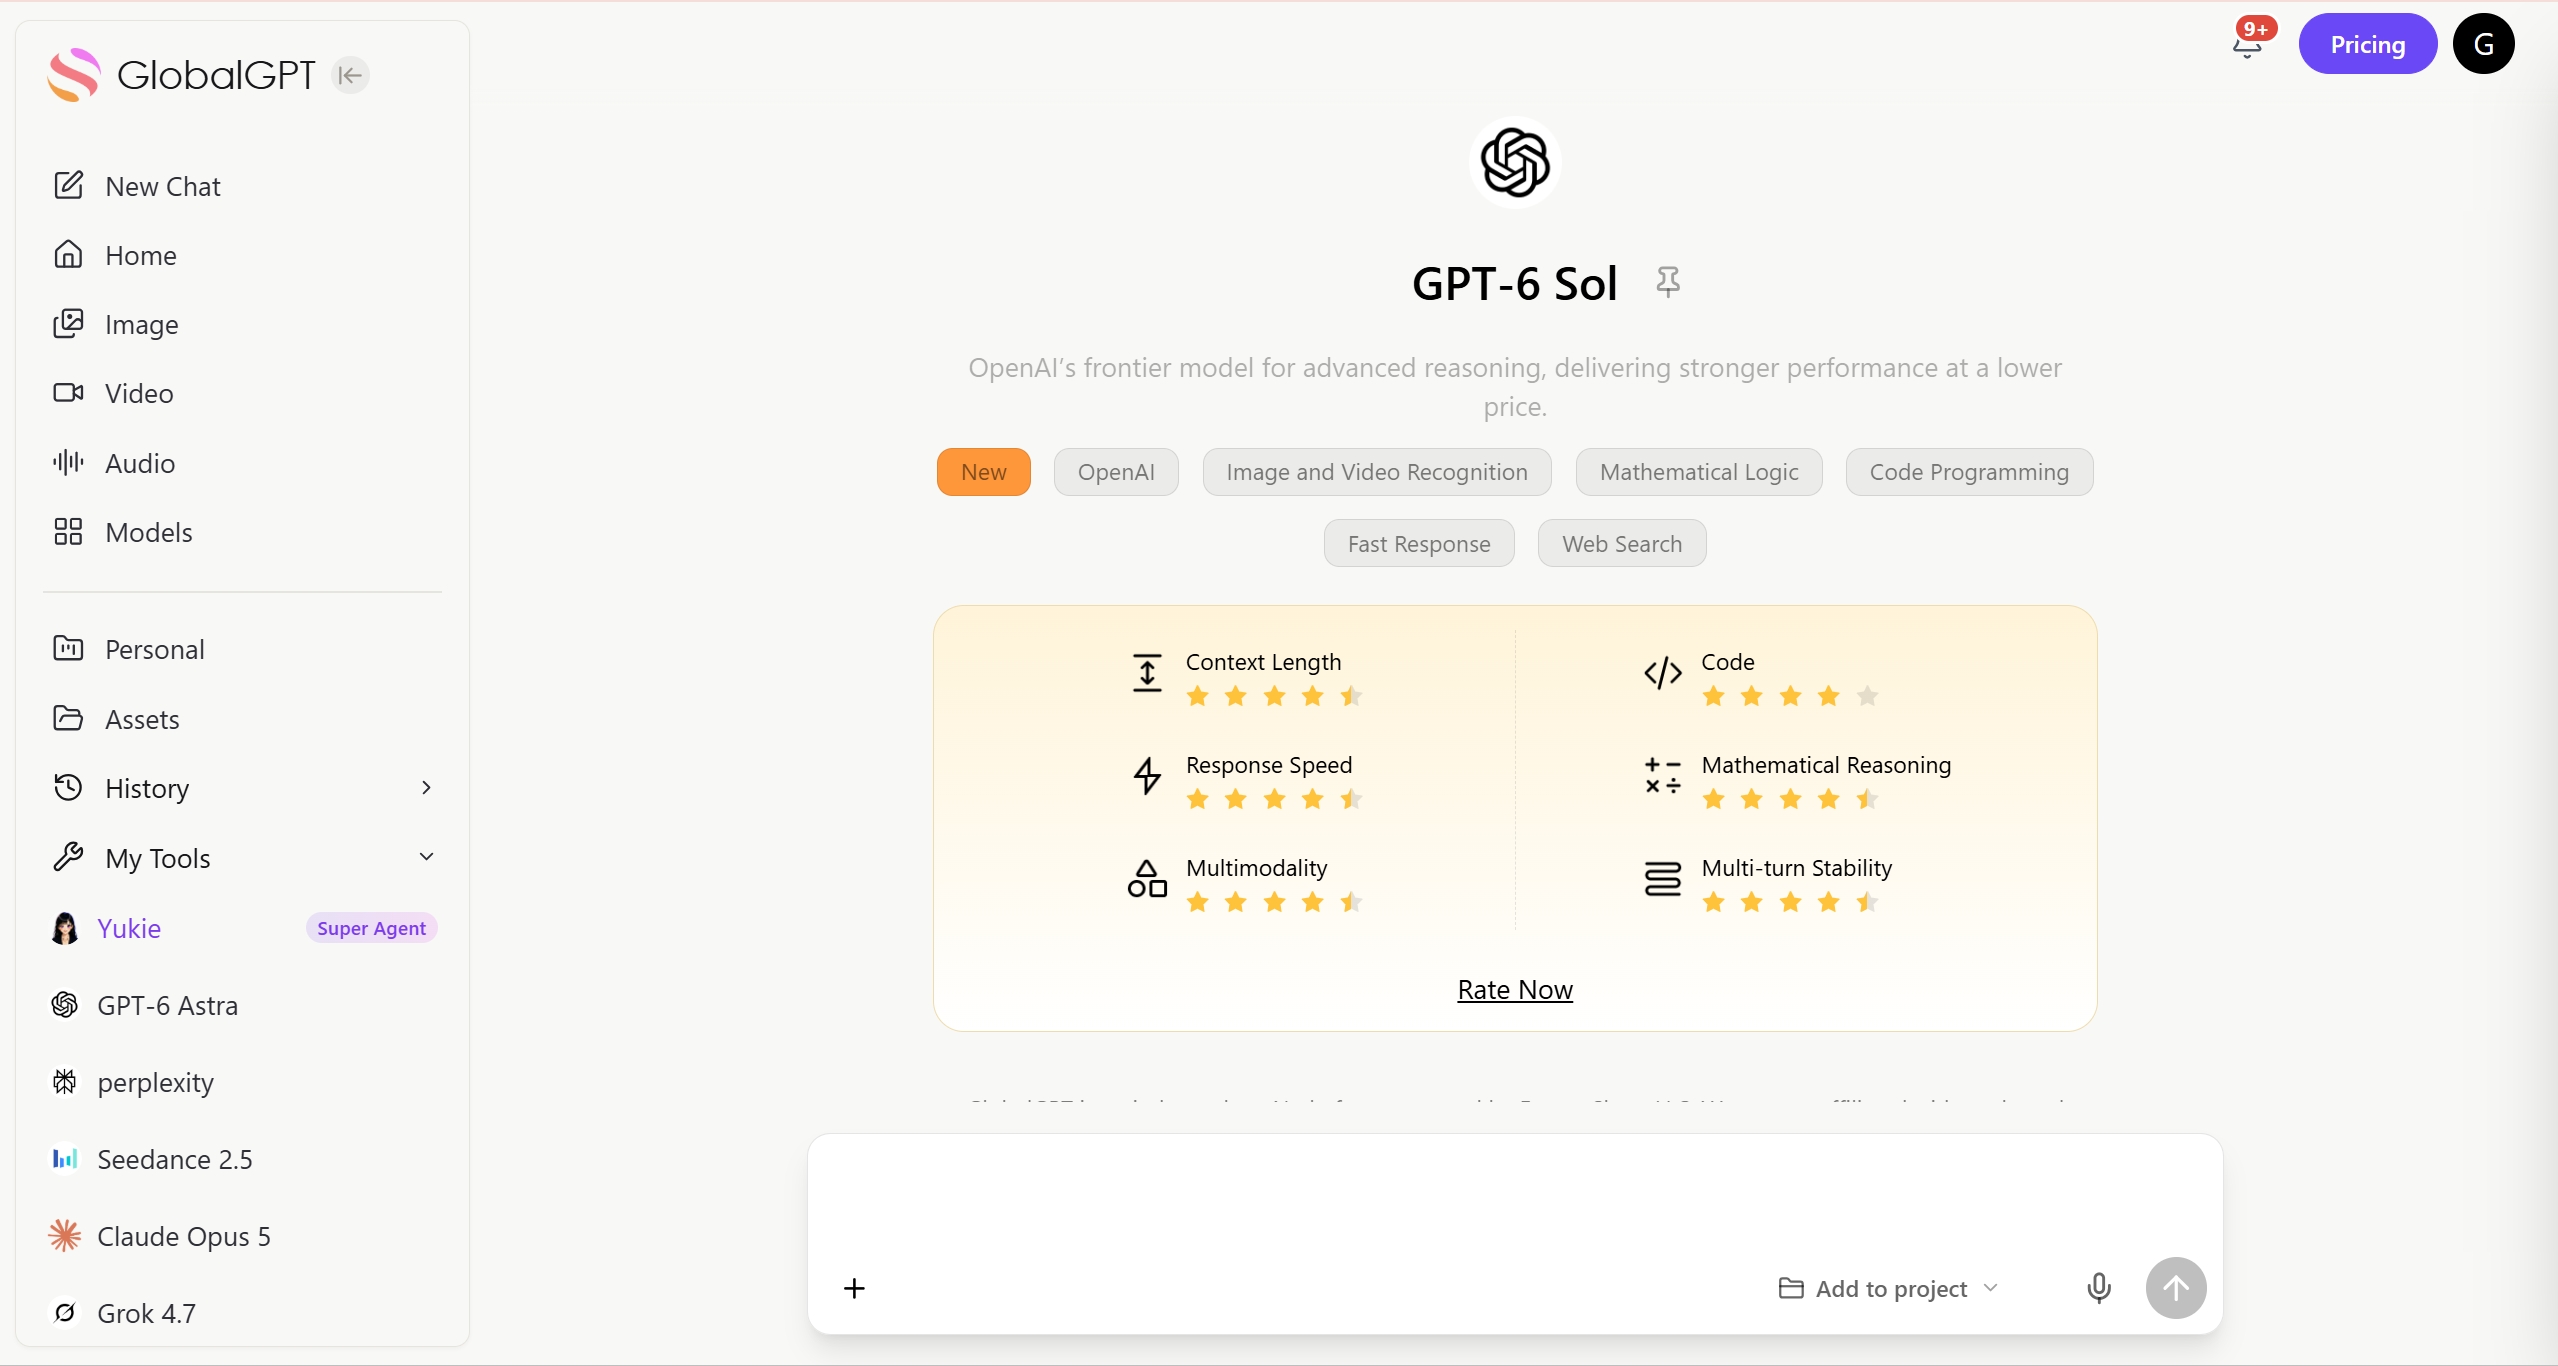
GlobalGPT’s verified model catalog currently exposes GPT-5.6 Sol そして GPT-5.6 Luna. The exact OpenAI API IDs in this article are gpt-6-sol and belong to OpenAI’s official documentation. An exact /home/gpt-6-sol GlobalGPT route was not verified, so this article does not claim that the platform route is GPT-6 access.
For the current platform naming and separate credit context, see the GPT-5.6 価格ガイド そして GPT-5.6モデルの比較. Those pages are platform/editorial context; they do not override OpenAI’s API pricing table.
This link opens GlobalGPT’s current platform naming, not a verified GPT-6 OpenAI model ID.
Open GlobalGPT GPT-5.6 Sol workspaceWho should choose GPT-6 Sol?
If your shortlist includes lower-cost alternatives, compare the broader model catalog rather than assuming the newest model is automatically the best value. If you are evaluating data-heavy work, the data-analysis model guide provides a separate workflow lens.
よくある質問
What is GPT-6 Sol?
GPT-6 Sol is OpenAI’s complex coding and agentic workflows model. Its official API model ID is gpt-6-sol.
How much does GPT-6 Sol cost?
OpenAI lists GPT-6 Sol at $2.00 per 1M input tokens, $0.20 per 1M cached input tokens, $2.50 per 1M cache writes, and $10.00 per 1M output tokens at Standard rates.
What happens above 272K input tokens?
When a request exceeds 272K input tokens, OpenAI applies 2x input and cache rates and 1.5x output rates to the full request.
What are the context and output limits?
GPT-6 Sol lists a 1,050,000-token context window, a 922,000-token maximum input, and a 128,000-token maximum output.
What is the knowledge cutoff?
The current OpenAI model page lists April 20, 2026 as the knowledge cutoff for GPT-6 Sol.
Which reasoning settings are available?
The API documents none, low, medium, high, xhigh, and max reasoning effort, with medium as the default.
Which API endpoints are supported?
GPT-6 Sol supports Chat Completions, Responses, and Batch. The model page does not list Realtime, Assistants, audio, video, image generation, embeddings, fine-tuning, moderation, or legacy Completions as supported.
Can GPT-6 Sol accept images?
Yes. The model page lists text and image input with text output. That does not make it an image-generation model.
Is GPT-6 Sol available in GlobalGPT?
OpenAI’s official model name is GPT-6 Sol, but GlobalGPT currently exposes GPT-5.6 Sol and GPT-5.6 Luna labels. The exact GPT-6 GlobalGPT route is not verified, so this article does not claim GPT-6 access through GlobalGPT.
Does this article include a benchmark?
Yes, but the scope is narrow: three matched tasks through the Broly Anywhere compatibility API. The results are retained as one observed run and are not an official OpenAI benchmark or a universal winner claim.
最終評決
Sol is the model to examine when the work is genuinely complex, tool-heavy, or code-centric and the higher token bill is acceptable. The evidence here combines official documentation with a scoped compatibility-API observation, not a controlled benchmark, so the responsible verdict is fit, not a universal ranking. Recheck the official model and pricing pages on publication day before publishing.
Checked September 23, 2026. Official facts: OpenAI Developers. Platform route naming: GlobalGPT. Public reaction: linked creators and publications, attributed only.