Updated September 18, 2026.
Our verdict: GPT-6 Astra returned usable answers in all three of our test calls: order reconciliation, a Python aggregation function, and a 500-note policy lookup. It handled missing values and conflicting rules correctly, and its generated function passed 10 offline checks. That makes it worth considering for careful analytical work—but three small tests do not establish production reliability or superiority over other models.
We called gpt-6-astra through GlobalGPT’s CLI-backed model service, using synthetic inputs and saving the raw responses. This was not a direct OpenAI API test or a ChatGPT subscription test. End-to-end calls took 4.87–9.07 seconds in this batch, and the account balance decreased by 391.08 credits.
This review shows what we asked, what Astra returned, what passed, and where the evidence stops. Official specifications and pricing appear separately from our measurements.

Contents
- GPT-6 Astra Hands-On Results
- How We Tested Astra Through the API Route
- Test 1: Can Astra Reconcile Messy Order Data?
- Test 2: Does Its Generated Code Actually Work?
- Test 3: Can It Resolve Conflicting Rules in a Long Packet?
- What These API-Route Tests Cost
- Is GPT-6 Astra available?
- GPT-6 Astra Specifications
- GPT-6 Astra API Pricing
- What Is Actually New in GPT-6 Astra?
- Why Astra Changes the Buying Decision
- What Early Reviewers Are Saying
- Early Limitations and Open Questions
- Who Should Use GPT-6 Astra?
- Choose Astra or a smaller model by the task
- What This Review Still Does Not Prove
- Frequently asked questions
GPT-6 Astra Hands-On Results
| Test | Observed result | Route time | Input / output tokens | Ledger credits |
|---|---|---|---|---|
| Order reconciliation | 5/5 answer checks passed | 5.663 s | 2,171 / 144 | 67 |
| Python aggregation function | 10/10 offline cases passed | 9.065 s | 2,091 / 486 | 105 |
| 500-note policy packet | 6/6 answers correct; required sources present for all six | 4.868 s | 17,445 / 160 | 219 |
These are three different tasks with one model call each, not repeated trials or a measured 100% success rate. Timing covers the complete CLI/provider request until the result returned; we did not measure time to first token. The ledger displays whole credits, while the balance change includes fractions.
How We Tested Astra Through the API Route
We used the same existing GlobalGPT account for all three calls. Each was a fresh, stateless request with the task supplied as a text file. The requested and returned model label was gpt-6-astra. The service returned answer text, input/output token usage and an error field; none of the three results reported an error. Provider labeling is not an independent audit of the upstream model route.
We prepared the order answer key and policy-packet answers before the calls. We then validated the generated code locally with 10 cases constructed after receiving it; these were not a preregistered coding benchmark. We requested JSON in the prompt and checked whether it parsed, rather than enabling a native structured-output schema.
All inputs were invented. No customer records, company files, account secrets or personal data were sent. We did not provide browsing or computer-control tools to the tasks, and we did not retry an answer to improve its score. The CLI did not expose the reasoning-effort setting or cached-token breakdown for these runs.
Test 1: Can Astra Reconcile Messy Order Data?
The task and answer key
The eight-row CSV included an older duplicate, a newer replacement, a pending order, refunds, and one order with no gross amount. The rules were to keep the newest version of each order, exclude pending payments, subtract refunds, and preserve missing revenue as unknown.
The expected known net revenue was $275: Search $170, Email $75, and Social $30. Order A needed deduplication, C needed exclusion, and F had to remain unknown. A correct total alone was not enough to pass all five checks.
What Astra returned
{"known_net_usd":275,"channel_known_net_usd":{"Search":170,"Email":75,"Social":30},"unknown_order_ids":["F"],"excluded_order_ids":["C"],"replaced_order_ids":["A"]}
All five checks passed. More usefully, its conclusion said: “Total net revenue remains unknown because order F has missing gross revenue.” It correctly called Search the largest known subtotal, without claiming the missing Email order was worth zero.
Our assessment: this was a good result for a compact reconciliation task. The model followed the accounting rules and preserved uncertainty. It was not a test of a live spreadsheet connection, thousands of transactions, tax compliance, or autonomous financial decisions.
Test 2: Does Its Generated Code Actually Work?
Replace a faulty revenue calculation
We supplied the faulty pattern sum(float(r.get('gross_usd') or 0) for r in records) and asked for a pure Python function that handles duplicate updates, payment status, refunds, missing values, sorted ID lists and empty input. It had to use integer cents internally and leave the input records unchanged.
Astra returned a function that uses Decimal to convert amounts into cents, keeps the latest record per order, and skips unknown gross amounts instead of inserting zero. We decoded newline escapes in the returned code string, reviewed its imports and operations, and executed it locally without changing its logic.
Ten offline checks
| Case | Result |
|---|---|
| Original eight-row reconciliation | Pass |
| Empty input | Pass |
| Newer record appears before older record | Pass |
| Latest update changes an order to pending | Pass |
| Blank and null gross amounts | Pass |
| Missing refund defaults to zero | Pass |
| 0.10 + 0.20 cent arithmetic | Pass |
| Full and partial refunds | Pass |
| A channel with only unknown revenue | Pass |
| Sorted unknown and excluded IDs | Pass |
Input immutability also held in all 10 cases. Our assessment: the function was usable for the stated contract, and the local execution provided stronger evidence than a plausible code sample alone. We did not test malformed timestamps, multiple currencies, deployment, a real repository, database transactions, or performance at scale.
Test 3: Can It Resolve Conflicting Rules in a Long Packet?
Five relevant notes among 500
We constructed a 73,252-character packet with 500 numbered notes. The relevant facts were spread across notes 037, 114, 261, 398 and 477: an old 30-day refund rule, a newer 14-day standard rule, a 30-day enterprise exception, an owner change, annual-versus-monthly-equivalent pricing, and a question for which the evidence was missing.
The complete request reported 17,445 input tokens. This is a modest long-document check, far below Astra’s advertised 1.05M-token capacity. Background notes were simple distractors, so it was easier than a messy real-world document collection.
Correct rules, prices and uncertainty
| Question | Astra’s answer | Required evidence |
|---|---|---|
| North standard refund window | 14 days | 114 |
| North enterprise refund window | 30 days | 477 |
| Current North owner | Lin | 114 |
| Atlas annual payment | $129.60 | 261 |
| Atlas monthly equivalent | $10.80 | 261 |
| South cash-refund entitlement | null / unknown | 398 |
All six answers were correct and included the required supporting notes. For the standard refund answer it additionally cited the enterprise-exception note, which was relevant context. It returned note identifiers as strings; no numeric-ID schema had been required.
Our assessment: Astra resolved the revision and exception correctly and did not invent the missing entitlement. That is useful evidence for bounded policy synthesis. It does not validate live research, arbitrary legal documents, needle retrieval near a million tokens, or resistance to malicious instructions embedded in sources.
What These API-Route Tests Cost
The three runs reported 21,707 input tokens and 790 output tokens. GlobalGPT’s ledger displayed 67, 105 and 219 credits; the account balance moved from 15,477.71 to 15,086.63 credits, a decrease of 391.08 credits. We do not convert those credits into an invented cash charge.
For a separate budgeting illustration, applying OpenAI’s short-context Standard rates of $10 per million uncached input tokens and $50 per million output tokens to those reported counts gives approximately $0.2566: $0.0289 for orders, $0.0452 for code and $0.1825 for the packet. This assumes uncached input and no additional charges. It is not the bill for our GlobalGPT calls or a measured direct-OpenAI cost.
The packet run was faster than the code run in this batch, despite having more input tokens. One run per task cannot establish a latency ranking: output length, routing, queueing and processing conditions can all differ. We did not run a matched competitor comparison.
Is GPT-6 Astra available?
Yes. Astra is listed in GlobalGPT’s catalog, and all three new calls returned a result labeled gpt-6-astra. OpenAI also publishes API model documentation; Chat, Work and Codex access are separate product entitlements.
The September 4 screenshots below belong to the launch period. Their rollout wording is historical, not evidence that today’s GlobalGPT entry is unavailable.
GPT-6 Astra Specifications
Astra accepts text and image inputs and produces text output. Its 1.05M-token context window matches the scale needed for large repositories, document collections, or long agent histories, while the 128K output ceiling gives it room for substantial code or reports.
Capacity is not the same as quality. A million-token window does not guarantee that every detail will be recalled equally well, and sending the maximum amount of context can increase both cost and noise. For practical long-context work, retrieve the most relevant files first and keep the task instructions explicit.
If you want a baseline for how the previous generation handled large prompts, see the GPT-5.5 pricing and context guide. For a broader task-oriented view, the GPT-5.5 use cases guide helps identify workloads that may justify a flagship model.
GPT-6 Astra API Pricing
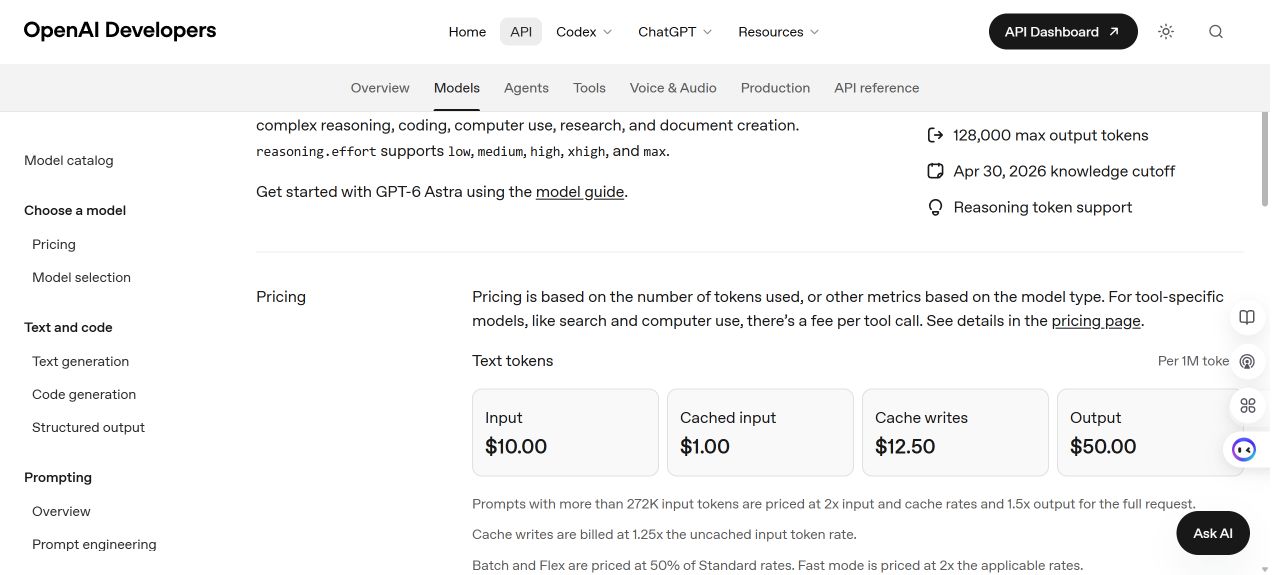
OpenAI lists the following Standard processing rates for prompts up to 272,000 input tokens:
Rates rechecked September 18, 2026 against OpenAI API pricing. These are Standard API token rates, not ChatGPT subscription prices or GlobalGPT credit charges.
| Token category | Price per 1M tokens | What it means |
|---|---|---|
| Input | $10.00 | New prompt content, history, retrieved material, and other billable input. |
| Cached input | $1.00 | Eligible repeated input served through prompt caching. |
| Cache write | $12.50 | Input written into the cache under the applicable cache-write pricing. |
| Output | $50.00 | Generated answer and billable reasoning output. |
Once a request exceeds 272,000 input tokens, OpenAI applies a 2x multiplier to input and cached-input rates and a 1.5x multiplier to output rates for the full request. At the listed Standard rates, that means $20 per million input tokens and $75 per million output tokens.
Pricing boundary:
These are OpenAI API token rates, not monthly ChatGPT subscription prices and not GlobalGPT credits. Tool charges, processing tiers, regional settings, and other fees may change the final cost.
For historical rate-card context, see GPT-5.6 pricing and GPT-5.4 pricing. Compare the full workload, not only the input rate: output length, cache behavior, tool use, and failure or retry rates can matter more than the headline price.
What Is Actually New in GPT-6 Astra?
OpenAI’s latest-model guide emphasizes a set of features aimed at long-running, interactive agent work.
Asynchronous tool calling
Astra can keep making progress while slower tools are still running instead of treating every tool call as a hard stop. That can help with research, coding, and operational tasks that combine several external systems with different response times.
Mid-task instructions
Users can add direction while a task is in progress. This is valuable when an agent is generally on track but needs a new constraint, a priority change, or a narrower scope. It should reduce the need to cancel a long run and start over.
Dynamic reasoning effort
Astra can adjust how much reasoning it applies during a task. In principle, that lets it spend more effort on difficult steps and less on routine ones. Teams should still test whether the quality gain is worth the added output-token cost for their own workload.
Computer use and long-task continuity
OpenAI positions Astra for computer interaction and work that unfolds over many steps. The practical question is not whether it can click through a demo, but whether it can recover from unexpected states, preserve the user’s intent, and explain what it changed. Those are the areas early adopters should evaluate.
Readers interested in the evolution from deliberative chat to tool-using systems can also review GPT-5.4 Thinking and this guide to using ChatGPT Agent.
Why Astra Changes the Buying Decision
The important shift is from evaluating an AI by the quality of one answer to evaluating whether it can complete an entire job. A useful agent may need to inspect files, operate software, wait for tools, recover from errors, apply a change, run checks, and explain the result. The final answer is only one part of that sequence.
That also changes the cost question. Astra’s token rates are high, but token price alone cannot tell you whether it is economical. A better comparison is cost per successfully completed task: model and tool charges, retries, elapsed time, human supervision, and cleanup all count. A cheaper model can cost more overall if it needs repeated correction; an expensive run is still wasteful if it wanders or produces work that must be redone.
Practical metric:
Track total cost, completion rate, human minutes, retries, and defects for the same representative task. Do not compare models from token rates or a single polished demo alone.
More autonomy also raises the standard for controls. OpenAI’s latest-model guidance says Astra is subject to asynchronous misalignment monitoring. Teams should still give an agent the minimum permissions it needs, require confirmation before consequential actions, keep an action record, and create checkpoints that make changes reversible. Strong computer use is valuable only when the surrounding system limits what can go wrong.
What Early Reviewers Are Saying
Attributed early experience
Matt Shumer’s early Astra review is one of the more detailed public accounts available at launch. He describes the model as strong at backend engineering, computer use, understanding underspecified requests, reporting its work clearly, and maintaining continuity across long conversations.
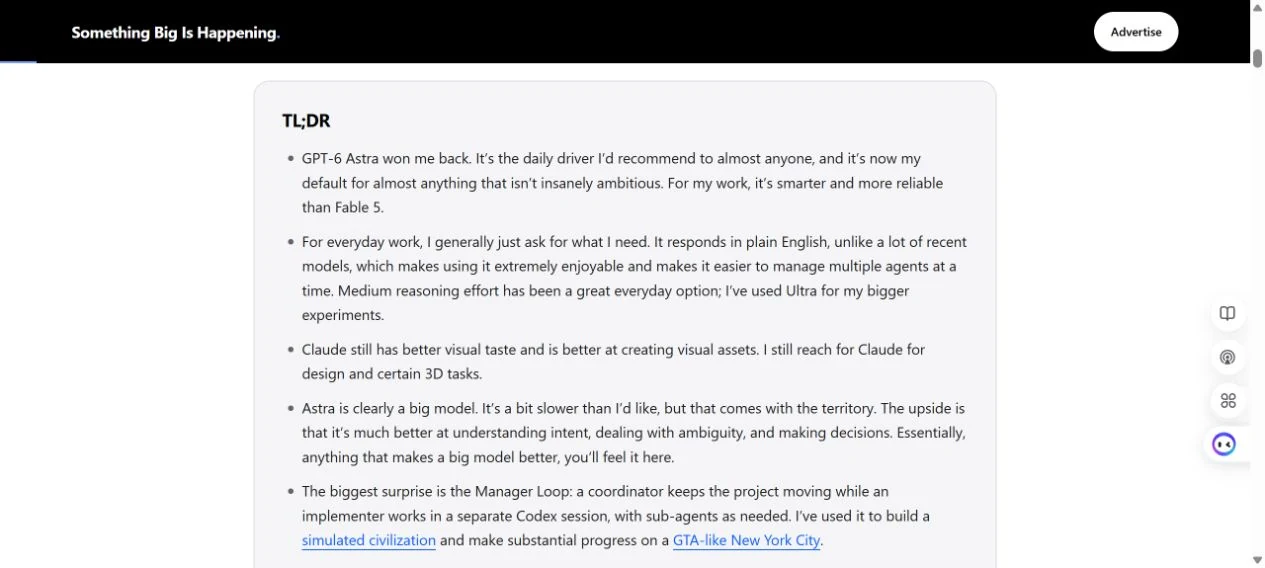
Backend engineering
The review highlights useful performance on complex implementation work, especially where the model must understand a system rather than produce a small isolated snippet.
Computer use
Astra reportedly handles browser and desktop-style tasks with more awareness of the broader objective, though that does not eliminate the need for permissions and verification.
Ambiguous intent
The model is described as better at inferring what a user is trying to accomplish from incomplete instructions.
Continuity and reporting
The review credits Astra with preserving context over long sessions and giving clearer accounts of what it has done.
These are qualitative observations from another reviewer. They help identify capabilities worth testing, but they are not our measurements and do not establish general reliability.
Early Limitations and Open Questions
The same review also raises important concerns. Astra can be slow, consume large amounts of tokens, and still get absorbed in details during long autonomous work. Shumer also reports that its visual design output may trail Claude, even when its backend work is strong.
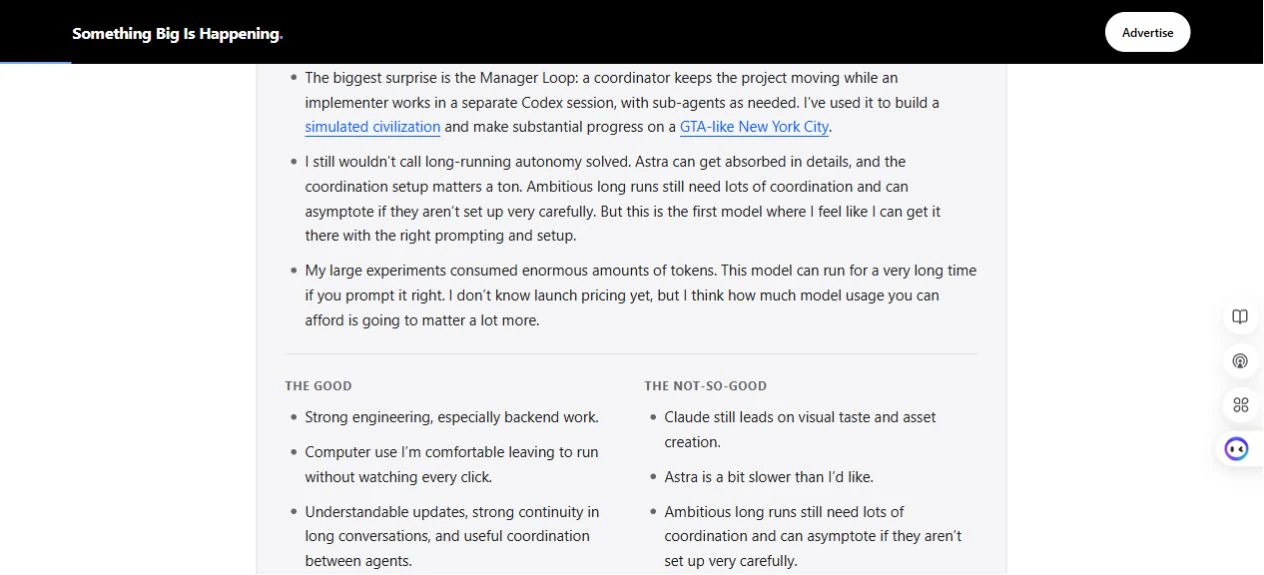
- Speed: A model that reasons, uses tools, and checks its work may take longer than a lightweight chat model.
- Autonomy: Long-running does not mean unsupervised. The reviewer still found moments where the model needed coordination or redirection.
- Token use: Large context and extended reasoning can become expensive quickly, especially above the 272K threshold.
- Visual design: Strong coding performance does not automatically produce the best interface aesthetics.
- Evidence depth: There are not yet enough independent, matched tests to make broad claims about reliability or superiority.
The key adoption test is therefore efficiency, not maximum capability. Measure how often Astra completes the whole task correctly, how much supervision it needs, how many tokens it uses, and how much cleanup remains. A slower expensive run can still be worthwhile if it replaces hours of expert work, but not if it repeatedly wanders.
Who Should Use GPT-6 Astra?
| Potential fit | Why Astra may help | What to verify first |
|---|---|---|
| Large codebase work | Long context, tool use, and continuity across multi-file changes | Regression rate, test discipline, review time, and token cost |
| Research and synthesis | Can coordinate retrieval, analysis, and long-form output | Citation accuracy, source coverage, and unsupported inference |
| Computer-use agents | Designed for multi-step interaction with software | Permission boundaries, recovery from UI changes, and action logs |
| Large document analysis | 1.05M context can hold substantial source material | Recall across the full context and whether retrieval is cheaper |
| Long-running operations | Mid-task steering and asynchronous tools can reduce restarts | Escalation behavior, checkpoints, and safe rollback |
Astra is less likely to be the right default for short rewrites, routine classification, simple extraction, or high-volume work where a smaller model already meets the quality bar. The GPT-5.4 and Nano review shows why model routing by task can be more economical than sending everything to the flagship model.
A practical evaluation checklist
- Choose three real tasks with clear success criteria.
- Run the same inputs and constraints on Astra and your current model.
- Record total elapsed time, input and output tokens, retries, and human corrections.
- Score final task completion separately from writing style or presentation.
- Test interruption, mid-task steering, and recovery from one deliberate tool failure.
- Adopt Astra only where the improvement is repeatable and worth the extra cost.
Choose Astra or a smaller model by the task
Use Astra for difficult synthesis and work where correctness is worth more than the lowest token price. A smaller model may be enough for routine extraction or a short rewrite. Compare successful completion, supervision and total cost on the same inputs.
For a multi-model workflow, GPT-6 Astra, Claude Opus 5, Claude Sonnet 5 and Gemini 3.8 Flash are listed in GlobalGPT’s current catalog. GlobalGPT is a separate subscription; it does not activate another provider’s paid account.
The GlobalGPT annual-plan page lists Basic at $5.80/month, Pro at $10.80/month and Unlimited at $25/month when billed annually, checked September 18, 2026. Compare the upfront commitment and included model usage, not just the smaller monthly equivalent.
What This Review Still Does Not Prove
An earlier Astra attempt through the same CLI route exited without an answer. We retain that failure in the test archive; it was not a quality score. The three successful calls here show that the route worked for this batch, not that the earlier failure cannot recur.
We did not test computer use, asynchronous tool calling, mid-task steering, million-token recall, native ChatGPT plan access, or unattended production work. There is no basis here for claiming Astra beats Claude, Gemini or a smaller OpenAI model. Those comparisons need matched tasks and repeated trials.
Buying recommendation: trial Astra on work where checking rules, missing values and exceptions matters. Keep a smaller model for routine tasks that already meet your quality target. Judge the additional cost by fewer corrections and usable finished work, not the model name alone.
Frequently asked questions
Was this a direct OpenAI API test?
No. We used GlobalGPT’s CLI-backed model service with gpt-6-astra. The reported token counts and credits belong to that route; the OpenAI dollar calculation is a separate rate-card illustration.
Is GPT-6 Astra available on GlobalGPT?
Yes. This review includes three successful gpt-6-astra calls through GlobalGPT’s model service. That platform subscription is separate from OpenAI’s API billing and ChatGPT plans.
What is the context window?
OpenAI lists 1,050,000 tokens of context, a maximum of 922,000 input tokens and 128,000 output tokens.
Does Plus have GPT-6 Pro in Chat?
The September 10 model guidance places GPT-6 Pro in eligible Pro, Business and Enterprise Chat plans. Plus includes Astra in Work and Codex; those are separate product entitlements.
How does long-input pricing work?
The official model page applies higher rates to the full request above 272,000 input tokens: 2x input and cache rates and 1.5x output rates.
Did the new test cover computer use?
No. We tested synthetic order analysis, code generation with local execution, and a 500-note text packet. Computer use, asynchronous tools and million-token reliability were not tested.
Should I replace every model with Astra?
No. Compare completion quality, manual checking, latency and cost for your own tasks. A small model can be the better choice when it reliably produces the same usable answer.