Quick answer: GPT-6 Luna is OpenAI’s focused, high-volume tasks model. The official API lists $0.10 per 1M input tokens and $0.50 per 1M output tokens at Standard rates, with a 1.05M-token context window and 128K maximum output. The strongest buying question is whether its answers meet your task requirements at an acceptable total cost.
OpenAI describes GPT-6 Luna as its most efficient model for focused, high-volume tasks. That phrase is provider positioning, not a measured quality score. This review translates the published specification into buying and architecture decisions, then records public reaction with attribution. We also ran three small tasks with the model ID, route, prompt set, raw output, and usage retained. The task results are shown below as one observed run, not as an official benchmark.
Quick verdict
Luna is the pragmatic cost-first option on the official price sheet: it keeps the same headline context and output ceilings as Sol while charging a fraction of the token rates. That makes it compelling for focused, repeated calls, but the low price is not proof of lower latency or lower quality without a controlled test.
The most useful distinction is not simply “smart” versus “fast.” It is workload shape. GPT-6 Luna has the same headline context and output ceilings as its sibling, but its positioning and price make a different operating point sensible. Compare the broader AI model selection guide and the best AI model for coding guide when the task spans more than one provider.
GPT-6 Luna at a glance
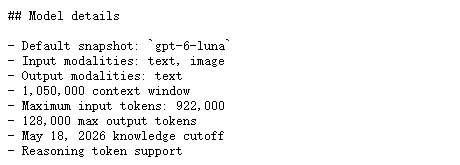
The table below follows the current official GPT-6 Luna model page. Context capacity is not the same thing as a recommended prompt size, and the maximum input is separate from the headline context window.
gpt-6-lunaBoth sibling models support structured outputs, function calling, streaming, prompt caching, image input, file search, and web search in the documented feature set. The exact tool behavior still depends on endpoint, account, and request configuration; do not infer a successful tool run from a capability checkbox.
For family-level context, the GPT-6 Astra review shows how a related GPT-6 article separates provider documentation, platform routes, and attributed reactions.
GPT-6 Luna pricing and the 272K rule
At Standard rates, the OpenAI pricing page lists $0.10 input, $0.01 cached input, $0.125 cache writes, and $0.50 output per 1M tokens. Cache writes are 1.25x uncached input. Batch and Flex are priced at 50% of Standard, Fast mode is 2x the applicable rate, and regional processing adds 10% where available.
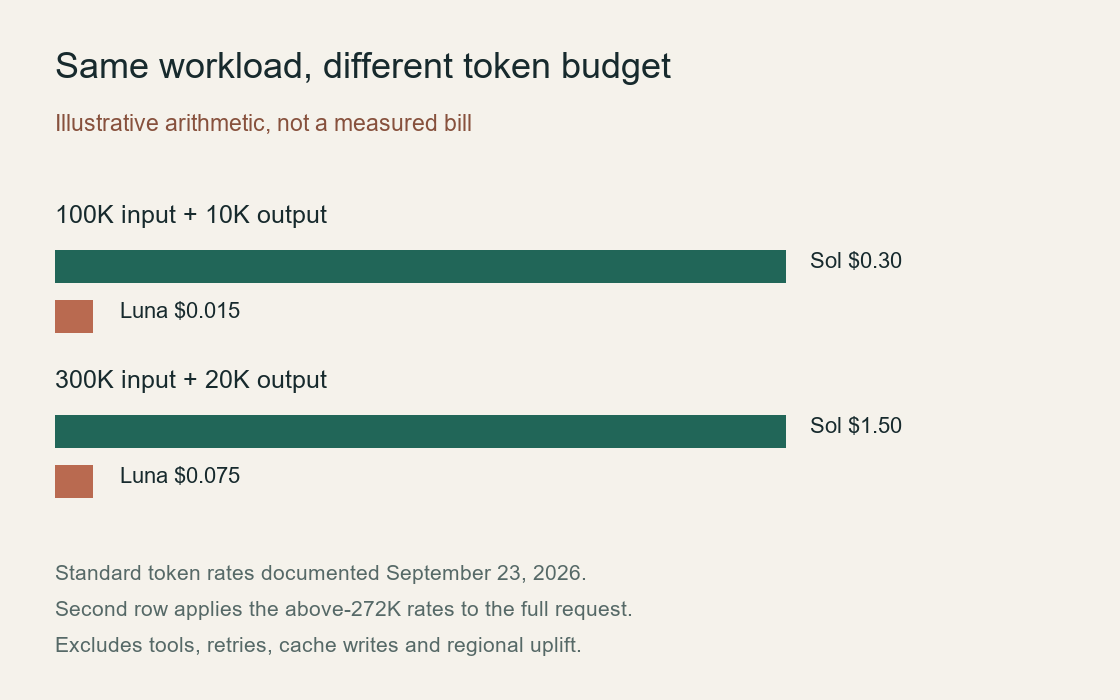
The long-context column is calculated from OpenAI’s rule: above 272K input, input and cache rates double and output is multiplied by 1.5 for the full request. It is not a mixed-rate bill. For a practical budget baseline, 100K input plus 10K output costs about $0.015 before tools or regional uplift; a 300K input plus 20K output example costs about $0.075 at the long-context rates.
A large context window can be useful without being cheap to fill. Retrieval, chunk selection, cache reuse, and output caps matter more than the headline 1.05M number. See the GPT-6 Astra pricing breakdown for a related explanation of context thresholds and cache mechanics.
GPT-6 Luna API fit, tools, and limits
OpenAI recommends the Responses API for built-in tools and function calling. Chat Completions supports function calling only when reasoning_effort is set to none. That is an implementation detail worth catching before migration: a request can be syntactically valid yet fail to match the tool behavior your current integration expects.
The current rate-limit table lists the following Standard tiers. RPM means requests per minute, TPM means tokens per minute, and the queue value is the batch-token limit.
Before production rollout, validate the exact tier, endpoint, streaming mode, and tool contract in your own account. The Codex usage limits guide is useful context for why a model’s published ceiling is not the same as an account’s live allowance.
What GPT-6 Luna’s specs imply
This is a fit map, not a benchmark. Use the all-in-one AI models workflow guide when your real decision is how to switch models inside one repeatable process rather than which single model sounds strongest.
In our tests: GPT-6 Luna on three practical tasks
We tested a small JavaScript repair, a three-note decision memo, and JSON extraction on September 23, 2026. The retained results below are complete responses for model ID gpt-6-luna. Earlier attempts encountered temporary overload errors, so these results should not be read as first-attempt reliability measurements. We examine what the answers contain, what a reader can reuse, and what remains untested.
Code repair: preserving zero without rewriting the function
The coding task asked for a bug diagnosis, minimal patch, and two regression tests. The result shown is the completed retry; its exact prompt wording is unavailable.
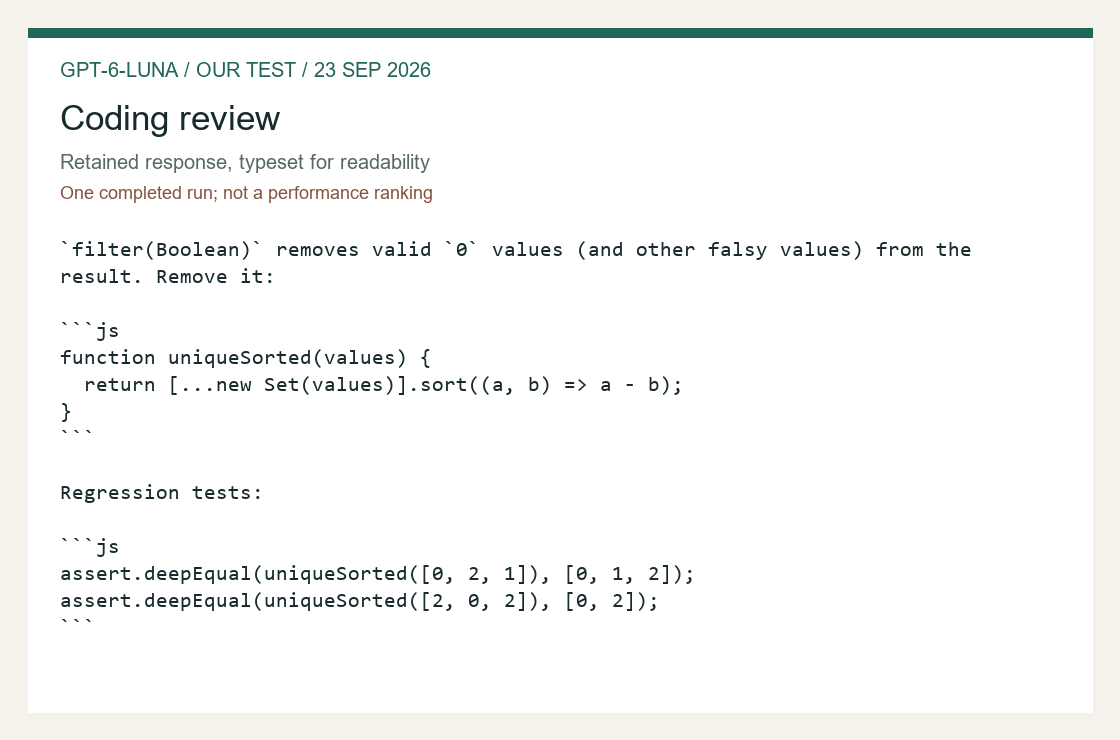
`filter(Boolean)` removes valid `0` values (and other falsy values) from the result. Remove it:

```js
function uniqueSorted(values) {
  return [...new Set(values)].sort((a, b) => a - b);
}
```

Regression tests:

```js
assert.deepEqual(uniqueSorted([0, 2, 1]), [0, 1, 2]);
assert.deepEqual(uniqueSorted([2, 0, 2]), [0, 2]);
```
Reported usage for this completed response: 61 input tokens, 317 completion tokens, 378 total tokens. Completion usage may include reasoning tokens; it is not simply the visible answer length.
Luna’s completed answer correctly identified that filter(Boolean) deletes valid zero values and removed that final operation. The response kept the existing Set-based deduplication and numeric comparator. For a narrowly scoped maintenance ticket, this is a useful output shape: a short explanation followed by the exact function. There was no unnecessary API redesign, new package dependency, or unrelated formatting pass to obscure the repair.
The integration gap is in the tests. Luna used assert.deepEqual twice but did not include an assert import. Pasting those statements into a fresh Node.js file would fail before either assertion runs. The assertions themselves target relevant combinations of zero, sorting, and duplicates, but the example is not self-contained. Add a strict assertion import or adapt the statements to your existing test runner. That is a small repair, yet it illustrates why a plausible code answer and a ready-to-run artifact are different acceptance criteria.
The retained coding answer is a retry. An earlier attempt reached its 900-token output cap; the completed retry used a shorter prompt and a 1,200-token cap. The exact retry wording was not retained, so we do not present the original coding prompt as if it produced this answer. This prevents a clean like-for-like quality or latency comparison with Sol. It also gives a practical deployment lesson: record the prompt version and finish reason, and never treat a truncated response as a successful code patch.
Three-note synthesis: keeping the decision conditional
Synthesize the following three notes into a concise decision memo with: decision, evidence, risks, and next step. Note A: A 1.05M-token context window can hold large source sets but does not make every request cheap. Note B: Above 272K input tokens, the documented input/cache rates increase and output is multiplied for the full request. Note C: Retrieval and cache reuse can reduce repeated prompt cost, but acceptance criteria still need testing.
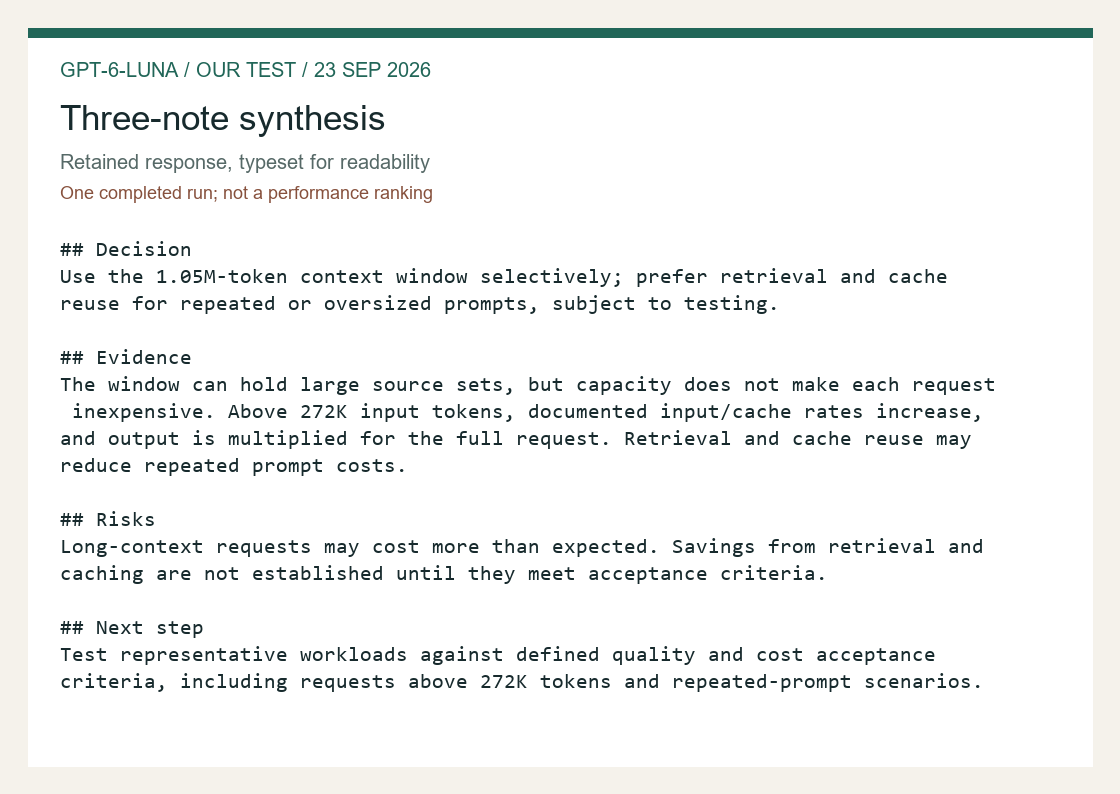
## Decision
Use the 1.05M-token context window selectively; prefer retrieval and cache reuse for repeated or oversized prompts, subject to testing.

## Evidence
The window can hold large source sets, but capacity does not make each request inexpensive. Above 272K input tokens, documented input/cache rates increase, and output is multiplied for the full request. Retrieval and cache reuse may reduce repeated prompt costs.

## Risks
Long-context requests may cost more than expected. Savings from retrieval and caching are not established until they meet acceptance criteria.

## Next step
Test representative workloads against defined quality and cost acceptance criteria, including requests above 272K tokens and repeated-prompt scenarios.
Reported usage for this completed response: 99 input tokens, 223 completion tokens, 322 total tokens. Completion usage may include reasoning tokens; it is not simply the visible answer length.
Luna kept all four requested memo sections and made its recommendation conditional on testing. It preserved the distinction between holding a large source set and processing it economically. It also said retrieval and caching savings are not established until they meet acceptance criteria. That restraint is useful for recurring internal summaries, where an attractive recommendation can otherwise become an unsupported promise after several rounds of rewriting.
The task contained three short notes and only 99 reported prompt tokens. Calling it a long-context benchmark would overstate what happened. The response shows that Luna can organize a tiny supplied evidence packet in this run; it does not establish retrieval recall, document coverage, resistance to conflicting instructions, or correctness near the maximum input size. Before using it for recurring summaries, include cases with contradictory dates and missing owners, then check whether uncertainty survives the final wording.
JSON extraction: keeping unknowns explicit
Extract the following fields from this brief and return valid JSON only with keys customer, priority, deadline, and unknowns. Brief: Customer: Northwind Labs. Priority: high. Deadline: 2026-10-04. The owner is not named and the budget is not confirmed.
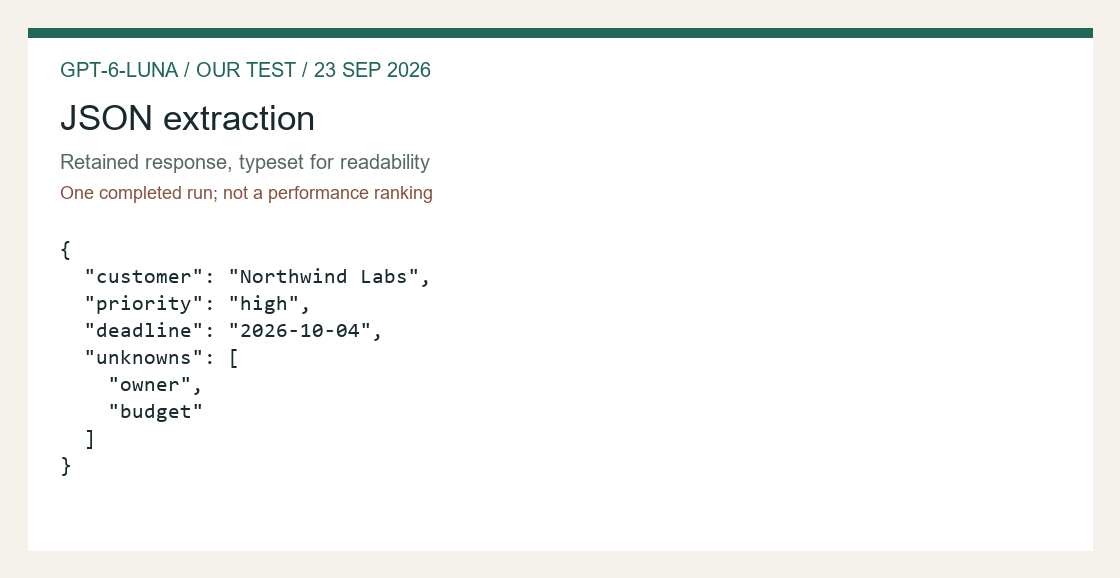
{"customer":"Northwind Labs","priority":"high","deadline":"2026-10-04","unknowns":["owner","budget"]}Reported usage for this completed response: 64 input tokens, 63 completion tokens, 127 total tokens. Completion usage may include reasoning tokens; it is not simply the visible answer length.
The extraction output is the strongest concrete reason in this small sample to consider Luna for narrow repeatable work. It returned valid JSON with the requested keys, copied Northwind Labs and the ISO-style deadline correctly, and preserved owner and budget as unknowns. There was no conversational prefix to strip. Sol produced the identical JSON on the same extraction prompt, so the available evidence does not show an advantage from the more expensive model on this record.
Syntactic validity is only the first gate. A JSON parser will happily accept an invented owner, the wrong customer, or a valid-looking but incorrect date. A schema can constrain fields and types; it cannot prove that the content follows the source. For this task, checking the three known values against the brief and checking that the two missing fields remain unknown provides the semantic gate. At scale, route conflicts and uncertain dates to review rather than repairing them by guessing.
A validation check that goes beyond parseable JSON
The following is an editorial validation example, not an additional model response. It runs locally in Node.js and makes no model request. It checks the specific fixture discussed above; it is not a general assessment of the model.
const assert = require('node:assert/strict');
const response = '{"customer":"Northwind Labs","priority":"high","deadline":"2026-10-04","unknowns":["owner","budget"]}';
const value = JSON.parse(response);
assert.deepStrictEqual(Object.keys(value).sort(), ['customer','deadline','priority','unknowns']);
assert.equal(value.customer, 'Northwind Labs');
assert.equal(value.priority, 'high');
assert.equal(value.deadline, '2026-10-04');
assert.deepStrictEqual(value.unknowns, ['owner', 'budget']);
console.log('This fixture matches the brief. New inputs need their own expected values.');
The validator deliberately checks the expected facts as well as the key set. It will reject a response that adds a confident owner field or changes the date while remaining valid JSON. Those exact values belong to this fixture; a production validator must obtain expectations from the input contract, not hardcode Northwind Labs for every customer. Calendar validation and permission to update a record are separate checks. Passing this example means the retained answer matches this brief, not that every future extraction will be correct.
How GPT-6 Luna changes a real workflow
The headline specification matters only when it changes the way a team works. GPT-6 Luna is positioned for focused, high-volume tasks, so the first question is whether your workload benefits from that shape. If every request has a short input, a narrow output contract, and a clear acceptance test, the model can sit inside a repeatable pipeline. If the task is ambiguous, tool-heavy, or likely to require several rounds of correction, the surrounding orchestration matters as much as the model name.
For GPT-6 Luna, a useful production pattern is a two-pass route: first ask for a compact answer with explicit uncertainty, then send only the disputed or incomplete portion to a second pass. This limits wasted output tokens and makes failure visible. It also gives you a better comparison point against GPT-6 Sol: the question is not which name sounds stronger, but which route reaches the acceptance criteria with fewer retries.
A simple cost model before you ship
The official price table should be translated into the units your team actually buys: requests per day, average input tokens, cached prefix share, output tokens, and the percentage of calls that cross 272K input. A spreadsheet that tracks only the headline input price hides the long-context multiplier and the cost of retries.
This calculation is especially relevant when comparing GPT-6 Luna with GPT-6 Sol. A cheaper request can become expensive if it needs repeated repair passes; a more capable request can be wasteful when the task is deterministic extraction. The right baseline is a small sample of your own traffic with the same prompts, same schema, and same review rule.
Failure modes to check before adoption
A model page can tell you which endpoints and modalities are documented, but it cannot guarantee that your existing application will behave the same after migration. Check whether streaming events are parsed correctly, whether tool calls preserve state across retries, whether structured output rejects malformed fields, and whether your logging pipeline records the model ID and reasoning setting for every request.
The same gates make the hands-on observations in this review useful without turning them into a leaderboard. Our three tasks show how the route handled a small code defect, a decision memo, and strict JSON extraction. They do not establish latency, reliability at scale, or a universal quality ranking.
A decision framework for real teams
A model review is useful when it helps someone make a decision under constraints. For GPT-6 Luna, the most relevant constraints are request shape, review cost, context size, output format, and the consequences of a wrong answer. The provider description points toward focused, high-volume tasks, but a team still needs to translate that description into a route it can monitor. Start by writing down the job in one sentence, the input the model will receive, the output another system expects, and the human checkpoint that prevents a silent mistake.
The first mistake is choosing a model from a demo prompt. A demo rewards fluency and hides operational details such as retries, token accounting, tool permissions, and schema failures. A better comparison uses three representative jobs: one ordinary request, one difficult request, and one request that should be rejected or escalated. The result is not a single score. It is a small map of where the model saves time, where it needs supervision, and where another model—often GPT-6 Sol—is the cheaper or safer fit.
Start with the acceptance test
Write the acceptance test before you write the prompt. For code, the test may be a passing unit test or a patch that leaves the public API unchanged. For extraction, it may be valid JSON with every required key present and unknown values preserved explicitly. For a decision memo, it may be a fixed structure with evidence, risk, owner, and next step. The model can only be evaluated against a visible target. Without that target, a polished paragraph can look successful while quietly omitting the one field the downstream process needs.
A good acceptance test is narrow enough to run automatically and meaningful enough to protect the user. It should also make disagreement legible. If two outputs differ, the team should be able to point to a missing fact, an unsupported assumption, a malformed field, or an incorrect calculation. That is more actionable than saying one answer “felt smarter.” It is also the difference between a review that helps procurement and a review that merely repeats launch language.
Use the model name to choose a starting hypothesis. Use your acceptance test to decide whether the hypothesis survives contact with production.
Prompt design that matches the model profile
The same prompt should not be copied unchanged between every model. The task contract can stay stable, but the amount of context, reasoning instruction, and output constraint should match the route. For GPT-6 Luna, keep the system instruction short enough that it does not compete with the source material. State the role, the decision rule, the required output shape, and the conditions that require an explicit unknown or escalation.
For long documents, separate retrieval from judgment. First identify the passages that answer the question; then ask for the conclusion using only those passages and the stated criteria. This reduces the chance that a confident sentence is built from a distant, irrelevant detail. It also makes a 1.05M-token context window a tool rather than a default. Large context is valuable when the relationship between distant pieces of evidence matters. It is wasteful when the task can be solved with a small, well-selected packet.
For tool-using workflows, describe the boundary between the model and the tool. The model should decide whether a tool is needed, provide arguments in a strict schema, and explain what it will do with the returned value. The application should enforce permission, validate arguments, record the call, and decide whether a failed tool call is retryable. Treating the model as the entire application makes debugging harder and increases the blast radius of a wrong assumption.
A reusable four-part prompt
Context: give only the facts and documents the task needs. Goal: state the decision or transformation in one sentence. Constraints: specify format, exclusions, uncertainty handling, and tool limits. Check: ask the model to list missing inputs or contradictions before it finalizes the answer. This structure is short enough for repeated calls and explicit enough to compare across models.
When a large context window helps
The 1.05M-token headline is easy to repeat and easy to misuse. A context window tells you how much material can fit in a request; it does not tell you how much material should be sent, how well the model will use every passage, or what the request will cost. A long request can also make review slower because the team has more evidence to inspect and more room for a subtle instruction conflict.
Use the full window when the task genuinely depends on distant references: a contract with definitions separated from exceptions, a repository where interfaces and implementations are far apart, or a long research archive where the answer requires tracing a sequence. Use retrieval when the question is local, when the source set changes frequently, or when you want a compact citation trail. Use caching when a stable prefix is reused across many requests and the platform exposes enough usage detail to prove the cache is working.
The 272K threshold should be part of the architecture diagram, not a footnote in the pricing paragraph. A request that is safe below the threshold can become materially more expensive above it. Teams should log input tokens, cached tokens, output tokens, model ID, reasoning setting, and whether the request crossed the threshold. That log supports a real cost model and makes it possible to find accidental context inflation before it becomes a monthly surprise.
API migration questions that deserve a staging run
Before moving an existing integration to GPT-6 Luna, build a staging harness that replays a small, anonymized sample. Compare the final text, structured fields, tool calls, stop reasons, and token usage. Do not compare only the first screen of the response. A model can preserve the visible conclusion while changing a field name, omitting an error condition, or returning a tool argument that the application cannot safely execute.
Responses and Chat Completions are not interchangeable labels in an integration plan. Endpoint support, reasoning settings, tool behavior, streaming events, and error objects all affect the adapter. Pin the model ID in configuration, but keep it visible in logs and test reports. When a request fails, the record should show the endpoint, model, reasoning effort, prompt version, request size, and retry decision. That evidence lets an engineer reproduce a failure instead of debating whether the model was simply having a bad day.
Batch processing changes the economics and the operational rhythm. It can be appropriate for overnight classification, document preparation, or a queue of low-urgency transformations. It is a poor fit for an interactive action that needs a user-facing response. Fast and regional modes also change the price calculation. Treat those as explicit configuration choices and reflect them in the budget worksheet rather than burying them in a default.
Replay representative inputs, validate structured output, capture tool arguments, compare stop reasons, measure token usage, and test one failure path before changing the production default.
Quality, safety, and review cost
A lower token price does not automatically mean lower total cost, and a more expensive model does not automatically produce a better business result. Total cost includes retries, human review, incident handling, and the work required to repair downstream data. The useful metric is cost per accepted result, separated by task family. A route that is slightly more expensive per request can still win if it reduces repair work on high-impact tasks; a very cheap route can win decisively for deterministic extraction with strong validation.
Risk should be classified by action, not by model branding. Reading a public document and drafting a summary is different from changing a customer record, approving a payment, deleting data, or publishing a legal statement. Put irreversible actions behind a human checkpoint or a second independent validation step. Ask the model to identify uncertainty, but never treat a confidence-sounding sentence as a permission system.
Privacy and retention questions belong in the deployment review. Confirm what data is sent, how long logs are retained, who can inspect prompts, and whether the request contains secrets or personal information. Redact where possible, minimize context, and keep a clear record of which fields were removed. These controls apply whether the model is used through an official API or another compatible route.
How to compare GPT-6 Luna with GPT-6 Sol
A fair comparison keeps the task and acceptance rule constant while allowing each model to use its documented strengths. Run the same input packet, but record whether a model needs a different reasoning setting or a different endpoint. Report the differences plainly: one may produce a more complete patch, another may be cheaper for repeated extraction, and a third may be easier to integrate because its tool contract matches your current adapter.
Do not convert one successful task into a general ranking. Three small tasks are useful for discovering workflow questions, not for proving a universal winner. Repeat the task with several realistic inputs, include at least one adversarial or incomplete case, and decide in advance what counts as a pass. If the sample is too small to support a conclusion, say so. That boundary increases trust rather than weakening the review.
A staged rollout that keeps the decision reversible
Start with shadow traffic or a non-critical queue. Let the new route produce an answer while the existing route remains the source of truth. Compare acceptance rate, token cost, review time, and failure categories for a fixed period. Then move one task family at a time, keeping a rollback switch and a prompt version tag. A staged rollout turns a model choice into an observable engineering change instead of a one-day replacement.
During rollout, watch for changes that do not appear in a simple pass rate: longer outputs, more tool calls, more escalations, or more requests crossing the long-context threshold. A model can look accurate while consuming more budget or increasing operator workload. Add alerts for those dimensions and review them with the people who actually handle exceptions.
What success looks like
Success is a stable route with a known cost, a visible failure mode, and a review process that people can follow. It does not require pretending the model is perfect. It requires knowing which jobs it handles well, which jobs need another route, and how to stop or correct it when the input is incomplete. That is the practical standard behind the observations and documentation collected in this review.
What public reactions can and cannot tell you
The following sources are included as attributed public reaction, not as official documentation or controlled benchmark evidence. Their titles show what each creator chose to test or explain; they do not establish a market-wide result.
- Chase AI: GPT 6 Sol & Luna Are Here (And 50% CHEAPER!). Treat the framing and any demonstration as that creator’s experience, not as a universal score.
- Rob The AI Guy: ChatGPT Released GPT-6 Sol & GPT-6 Luna (New ChatGPT Models & Agents). Treat the framing and any demonstration as that creator’s experience, not as a universal score.
- AI with Surya: GPT-6 Soul vs Luna vs Claude Opus 5.5: Which Should You Use?. Treat the framing and any demonstration as that creator’s experience, not as a universal score.
A separate naming issue matters here: several public videos use “GPT-6” and “GPT-5.6” interchangeably in titles. Keep the exact model ID visible when you reproduce a claim. The GPT-6 Astra vs GPT-5.6 Sol comparison is a useful example of why provider identity, platform label, and route should be recorded separately.
How to access GPT-6 Luna
Open the GPT-6 Luna workspace to start with a task you can evaluate: a small code example, a short source packet, or a structured extraction brief. Keep the requested output and acceptance rule visible while comparing revisions. The official token prices above describe direct API usage, not a promise about workspace credits or subscription allowances.
For the current platform naming and separate credit context, see the GPT-5.6 pricing guide and the GPT-5.6 model comparison. Those pages are platform/editorial context; they do not override OpenAI’s API pricing table.
Bring a representative task and compare the result against your own acceptance criteria.
Open GPT-6 Luna workspaceWho should choose GPT-6 Luna?
If your shortlist includes lower-cost alternatives, compare the broader model catalog rather than assuming the newest model is automatically the best value. If you are evaluating data-heavy work, the data-analysis model guide provides a separate workflow lens.
Frequently asked questions
What is GPT-6 Luna?
GPT-6 Luna is OpenAI’s focused, high-volume tasks model. Its official API model ID is gpt-6-luna.
How much does GPT-6 Luna cost?
OpenAI lists GPT-6 Luna at $0.10 per 1M input tokens, $0.01 per 1M cached input tokens, $0.125 per 1M cache writes, and $0.50 per 1M output tokens at Standard rates.
What happens above 272K input tokens?
When a request exceeds 272K input tokens, OpenAI applies 2x input and cache rates and 1.5x output rates to the full request.
What are the context and output limits?
GPT-6 Luna lists a 1,050,000-token context window, a 922,000-token maximum input, and a 128,000-token maximum output.
What is the knowledge cutoff?
The current OpenAI model page lists May 18, 2026 as the knowledge cutoff for GPT-6 Luna.
Which reasoning settings are available?
The API documents none, low, medium, high, xhigh, and max reasoning effort, with medium as the default.
Which API endpoints are supported?
GPT-6 Luna supports Chat Completions, Responses, and Batch. The model page does not list Realtime, Assistants, audio, video, image generation, embeddings, fine-tuning, moderation, or legacy Completions as supported.
Can GPT-6 Luna accept images?
Yes. The model page lists text and image input with text output. That does not make it an image-generation model.
Is GPT-6 Luna available in GlobalGPT?
Use the dedicated GPT-6 Luna model page linked above. Workspace credits and plan allowances are separate from the direct API token rates described in this review.
Does this article include a benchmark?
It includes three small task observations, not a controlled benchmark. Luna needed a revised coding prompt on retry. These results do not establish a universal winner or performance at scale.
Final verdict
Luna is the pragmatic cost-first option on the official price sheet: it keeps the same headline context and output ceilings as Sol while charging a fraction of the token rates. That makes it compelling for focused, repeated calls, but the low price is not proof of lower latency or lower quality without a controlled test. Choose on the basis of accepted outputs and total operating cost, then revisit the choice when your workload changes.
Checked September 23, 2026. Official facts: OpenAI Developers. Platform route naming: GlobalGPT. Public reaction: linked creators and publications, attributed only.