
Claude Sonnet 5.5 vs Opus 5.5 : prix, benchmarks et tests en conditions réelles
Sonnet 5.5 and Opus 5.5 share the Claude 5.5 generation, but they are priced and positioned differently. This comparison puts both through the same five prompts and reports what the route actually returned.
The measured gap is mostly about cost and speed. In this five-prompt pack, Sonnet 5.5 finished faster, used fewer output tokens, and produced the lower arithmetic request-cost estimate. Opus 5.5 used more tokens and time, while its answers were often more expansive. The task cards show where that extra text changed the useful result and where both models simply passed.
The prompts, request ceiling, effort setting, endpoint, and one-run-per-model design were kept aligned with the previous Avis sur le Claude Opus 5.5.
Réponse rapide
- Speed in this matched run: Sonnet 5.5 finished five sequential requests in 31.930 seconds locally; Opus 5.5 took 47.725 seconds.
- Route-reported output tokens: Sonnet 5.5 used 2,686; Opus 5.5 used 3,952. Thinking fields were 987 and 2,214 respectively.
- Arithmetic list-price estimate: the five Sonnet requests came to about $0.02826; the five Opus requests came to about $0.08184, using official standard token rates and excluding cache, credits, tax, and markup.
- Task result: both models passed the extraction, JSON, and math prompts. Sonnet kept the requested two-paragraph Chinese format more cleanly; the coding outputs were both usable but differed in depth and edge-case explanation.
- API migration: thinking cannot be disabled; forced tool choice is rejected, and token budgets include thinking. Check the migration caveats before switching.
- Decision boundary: this is one run per task through a third-party route. It measures the observed prompt responses, local wall time, and route-reported usage—not a universal capability score.
Official price and model specs
Anthropic’s current model cards list both models with a 1M-token context window and a 128K maximum output. Sonnet 5.5 is labelled Rapide with high default effort; Opus 5.5 is labelled Modéré with medium default effort. The standard token rates make Sonnet 5.5 half the input and output price of Opus 5.5.
| Modèle | ID de l'API | Official latency label | Entrée / sortie | Contexte / puissance maximale | Effort par défaut | Lecture du cache |
|---|---|---|---|---|---|---|
| Claude Sonnet 5.5 | claude-sonnet-5-5 | Active · Fast | $2 / $10 par MTok | 1 Mo / 128 Ko | Haut | $0.20 / MTok |
| Claude Opus 5,5 | claude-opus-5-5 | Active · Moderate | $4 / $20 par MTok | 1 Mo / 128 Ko | Moyen | $0.20 / MTok |
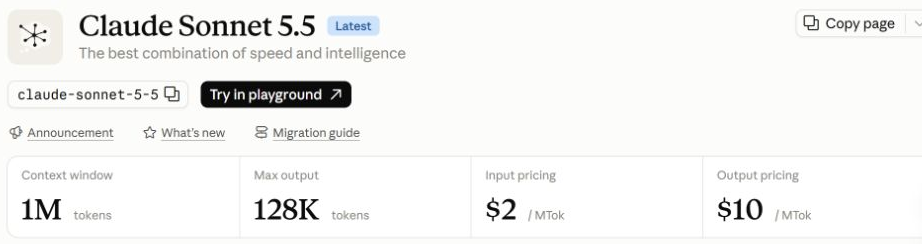
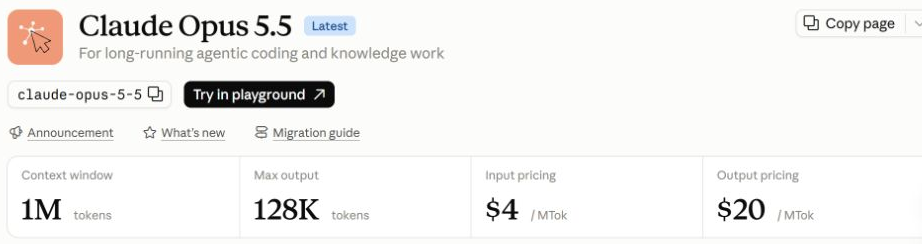
For a simple uncached example of 100,000 input tokens plus 20,000 output tokens, the listed token rates work out to about $0.40 on Sonnet 5.5 and $0.80 on Opus 5.5. See the Claude pricing and limits guide for plan context.
Official benchmark context
Anthropic’s Sonnet 5.5 announcement places both models in one provider-reported table. The row pattern is mixed by benchmark and effort setting.
| Anthropic-reported benchmark | Sonnet 5.5 | Opus 5.5 | Mesure |
|---|---|---|---|
| Terminal-Bench 4.0 | 70.6% | 66.4%¹ | Agentic terminal coding |
| FrontierCode v1.1 (Main) | 46.2% Max² / 52.1% Xhigh | 54.4% | Whether code changes would be merged |
| CursorBench 4.0 | 55.5% | 57.8% | Tâches de codage ambiguës portant sur plusieurs fichiers |
| GDPval-AA v2.1 | 1844 | 1846 | Knowledge work across occupations |
| Le dernier examen de l'humanité | 64.5% with tools | 67.7% with tools | Raisonnement multidisciplinaire |
| OSWorld 2.1 | 80.1% partial | 81.8% partial | Tâches impliquant l'utilisation d'un ordinateur |
| Chartography | 61.6% no tools | 64.4% no tools | Visual chart recognition |
¹ Opus 5.5 Terminal-Bench uses xhigh effort; ² Sonnet 5.5 FrontierCode is 46.2% at Max and 52.1% at Xhigh effort. OSWorld values are marked partial. These are provider context, not an equal-effort independent rerun.
Same-prompt API method
Each model received the same five prompts through POST https://anywhere.broly.ai/v1/messages. The client sent one user message, max_tokens: 8192, output_config.effort : élevé, and no tools. Every request returned HTTP 200 and fin_tour.
The testing approach follows the broader GlobalGPT model-testing workflow. A separate Guide de l'API Claude covers request setup and token accounting.
Time, tokens, and estimated cost
| Itinéraire | Five-run local time | Jetons d'entrée | Jetons de sortie | Reported thinking | Estimated request cost* |
|---|---|---|---|---|---|
| Claude Sonnet 5.5 | 31.930s | 700 | 2,686 | 987 | $0.02826 |
| Claude Opus 5,5 | 47,725 s | 700 | 3,952 | 2,214 | $0.08184 |
* Estimate from route-reported tokens and official standard rates. Sonnet 5.5 was 33.1% lower on local elapsed time and 32.0% lower on output-token count in this pack.
Cinq fiches d'activité assorties
Each card keeps the task, observation, local time, route-reported tokens, status, and boundary together.
Ces modèles permettent-ils de corriger une fonction de déduplication de type mixte ?
Configuration de la tâche : The exact prompt was copied from the earlier Avis sur le Claude Opus 5.5 test pack.
| Modèle | Time / route usage | Short result label |
|---|---|---|
| Claude Sonnet 5.5 | 8.679s 145 input / 830 output 0 thinking HTTP 200 · end_turn | Corrected function plus two tests; shorter explanation. |
| Claude Opus 5,5 | 15.844s 145 input / 1478 output 700 thinking HTTP 200 · end_turn | Corrected function plus two tests; more edge-case discussion. |
Observed comparison: Both returned a corrected function and two tests. Sonnet 5.5 used type-tagged keys, casefold(), and a list fallback in a shorter response; Opus 5.5 spent more output tokens explaining additional edge cases. Neither run establishes a general coding winner.
Limite : A single small Python repair checks concrete edge cases, not reliability across repositories or tool-driven coding.
Les modèles peuvent-ils conserver les cinq faits fournis sans ajouter d'affirmations ?
Configuration de la tâche : The exact prompt was copied from the earlier Avis sur le Claude Opus 5.5 test pack.
| Modèle | Time / route usage | Short result label |
|---|---|---|
| Claude Sonnet 5.5 | 3.569s 210 input / 209 output 0 thinking HTTP 200 · end_turn | Five numbered bullets; supplied facts preserved. |
| Claude Opus 5,5 | 4.374s 210 input / 312 output 101 thinking HTTP 200 · end_turn | Five numbered bullets; supplied facts preserved. |
Observed comparison: Both returned exactly five numbered bullets and stayed within the supplied facts. Sonnet 5.5 used 209 output tokens versus Opus 5.5’s 312, but the prompt was a short note rather than a large-context input.
Limite : This is a grounded extraction and formatting check; it is not evidence of million-token context performance.
Les modèles peuvent-ils renvoyer exactement la structure demandée ?
Configuration de la tâche : The exact prompt was copied from the earlier Avis sur le Claude Opus 5.5 test pack.
| Modèle | Time / route usage | Short result label |
|---|---|---|
| Claude Sonnet 5.5 | 5.052s 128 input / 260 output 0 thinking HTTP 200 · end_turn | Parseable JSON; requested keys and item counts. |
| Claude Opus 5,5 | 8.276s 128 input / 622 output 390 thinking HTTP 200 · end_turn | Parseable JSON; requested keys and item counts. |
Observed comparison: Both returned parseable JSON with the requested keys and two pros/two cons. Sonnet 5.5 was more concise at 260 output tokens; the strings describe a fictional review setup and are not product facts.
Limite : Passing this schema once does not measure structured-output reliability under tool calls or long conversations.
Les modèles sont-ils capables de conserver la séquence arrondie des lots jusqu'à la réponse finale ?
Configuration de la tâche : The exact prompt was copied from the earlier Avis sur le Claude Opus 5.5 test pack.
| Modèle | Time / route usage | Short result label |
|---|---|---|
| Claude Sonnet 5.5 | 2.947s 89 input / 163 output 0 thinking HTTP 200 · end_turn | Correct result: 67; final answer on its own line. |
| Claude Opus 5,5 | 3.830s 89 input / 257 output 74 thinking HTTP 200 · end_turn | Correct result: 67; final answer on its own line. |
Observed comparison: Both calculated 67 and placed the final answer on its own line. Sonnet 5.5 used 163 output tokens versus Opus 5.5’s 257, with no observed correctness difference on this prompt.
Limite : One arithmetic sequence cannot estimate broad reasoning reliability.
L'itinéraire peut-il conserver la structure en deux paragraphes demandée ?
Configuration de la tâche : The exact prompt was copied from the earlier Avis sur le Claude Opus 5.5 test pack.
| Modèle | Time / route usage | Short result label |
|---|---|---|
| Claude Sonnet 5.5 | 11.683s 128 input / 1224 output 987 thinking HTTP 200 · end_turn | Two Chinese paragraphs; no extra framing. |
| Claude Opus 5,5 | 15.401s 128 input / 1283 output 949 thinking HTTP 200 · end_turn | Covered the points; added Markdown and an English note. |
Observed comparison: Sonnet 5.5 returned the requested two Chinese paragraphs without extra framing. Opus 5.5 also covered the requested points but added Markdown framing and an English note. This records format following in one route run, not overall Chinese quality.
Limite : The prompt asks for an opening about Opus 5.5, so the text itself is not a neutral language benchmark.
Précautions concernant l'API et la migration
Sonnet 5.5 runs adaptive thinking by default; thinking: disabled returns a 400 error, and max_tokens covers thinking plus response text. Forced tool_choice any/tool is rejected. Parse content blocks by type and re-baseline token budgets before switching.
Ce que les données factuelles confirment
Verdict au niveau de la tâche
Sonnet 5.5: lower measured cost and time on this route, with clean format compliance on the Chinese task.
Opus 5.5 : more expensive and more expansive here; official benchmark rows remain ahead on several open-ended tasks.
Use the task-level evidence to choose a starting point, then validate the workload that matters to you.
For adjacent context, see the Claude family comparison, Opus 5 review, et Fable 5.1 review.
FAQ
Which model was faster in the matched test?
Sonnet 5.5 had the lower local total: 31.930 seconds versus 47.725 seconds for Opus 5.5 across five sequential requests. This includes the route and network path used here, so it is not provider-side latency.
Which model used fewer output tokens?
Sonnet 5.5 used 2,686 route-reported output tokens across the five tasks, compared with 3,952 for Opus 5.5. Token count alone does not prove answer quality.
Which model was cheaper in this run?
Using official standard API rates and the returned input/output counts, the five Sonnet 5.5 requests estimate to $0.02826, versus $0.08184 for Opus 5.5. The calculation excludes cache charges, platform credits, tax, and markup.
Does Sonnet 5.5 beat Opus 5.5 on every benchmark?
No. Anthropic’s own table is mixed by benchmark and effort setting: Sonnet 5.5 is higher on Terminal-Bench 4.0, while Opus 5.5 is higher on FrontierCode, CursorBench, GDPval-AA, Humanity’s Last Exam, OSWorld, and Chartography. These are provider-reported results, not an independent rerun.
Is Sonnet 5.5 a drop-in API replacement?
No. The migration guide says thinking runs by default, thinking: disabled returns a 400 error, forced tool choice any/tool is rejected, and clients should parse content blocks by type. Re-baseline token budgets and tool loops before switching.
S'agissait-il d'un test de performance à long terme ?
No. The extraction prompt contains a short passage. It checks factual grounding and exact formatting; it does not measure behavior near the documented 1M-token context window.



