

A fast, low-cost model for long-context agent work
MiniMax M3.1 Flash launched on October 19, 2026 with a 1M-token context window, adjustable thinking effort, multimodal input, and tool support. We tested three real tasks—exact JSON, JavaScript debugging, and HTTP 503 diagnosis—and all three completed successfully.
If you are comparing low-cost agent models for coding, tool use, or long documents, this guide puts the useful facts in one place: what the model can do, what the official scores actually mean, how to call it, how to estimate cost, and where access is currently visible. You can also compare the broader Les meilleurs modèles d'IA pour le codage list before choosing a default.
Try MiniMax M3.1 Flash on GlobalGPT through the general model workspace. The authenticated test route used for this article exposed the model as “MiniMax M3.1 Flash”; platform entitlements and model availability can change by account and region.

- What is MiniMax M3.1 Flash?
- Official benchmarks and speed claims
- API pricing and cost examples
- API setup: OpenAI-compatible and Anthropic-compatible
- Parameters, thinking, tools, and multimodal limits
- What our GlobalGPT tests returned
- Free access, M Plan, and MiniMax Code
- M3.1 Flash vs M3
- À qui s'adresse-t-il ?
- Verdict
- FAQ
What is MiniMax M3.1 Flash?
MiniMax M3.1 Flash is the company’s fast agent-oriented model for coding, computer-use workflows, tool calling, cybersecurity tasks, and long-context reasoning. The annonce de lancement dates the release to October 19, 2026, while the official invocation guide lists a 1M-token context window.
The word “Flash” describes the model’s speed and cost position, not a separate lightweight chat-only mode. Thinking is enabled by default and cannot be switched off in the documented API behavior. You can select a thinking effort level, which gives you a practical trade-off between response depth, latency, and output cost.
That makes the model interesting for repository tasks, structured planning, API troubleshooting, and agents that need to keep a large amount of context in one turn. It is still worth matching the model to the workload: for a useful model-selection framework, see this Guide des meilleurs modèles d'IA and compare the specific tool or coding constraints you have.
Official benchmarks and speed claims
The launch article publishes the following scores and positioning. They are MiniMax-reported figures, not independent reruns from this article. The right way to read them is as the provider’s release evidence and task coverage, not as a promise that every prompt will match a leaderboard result.
| Evaluation or claim | Published result | Comment l'interpréter ? |
|---|---|---|
| BankerToolBench | 76.2 | Tool-oriented work, reported by MiniMax |
| DeepSWE v1.1 | 73.7% | Software-engineering benchmark context |
| OSWorld V2 | 61.7 | Computer-use task performance context |
| Agents’ Last Exam | 29.6 | Agent evaluation context |
| CyberGym | 82% | Cybersecurity task context |
| Vitesse de sortie | 200+ TPS peak; 170+ TPS P50 | Provider-reported throughput claim, not our latency test |
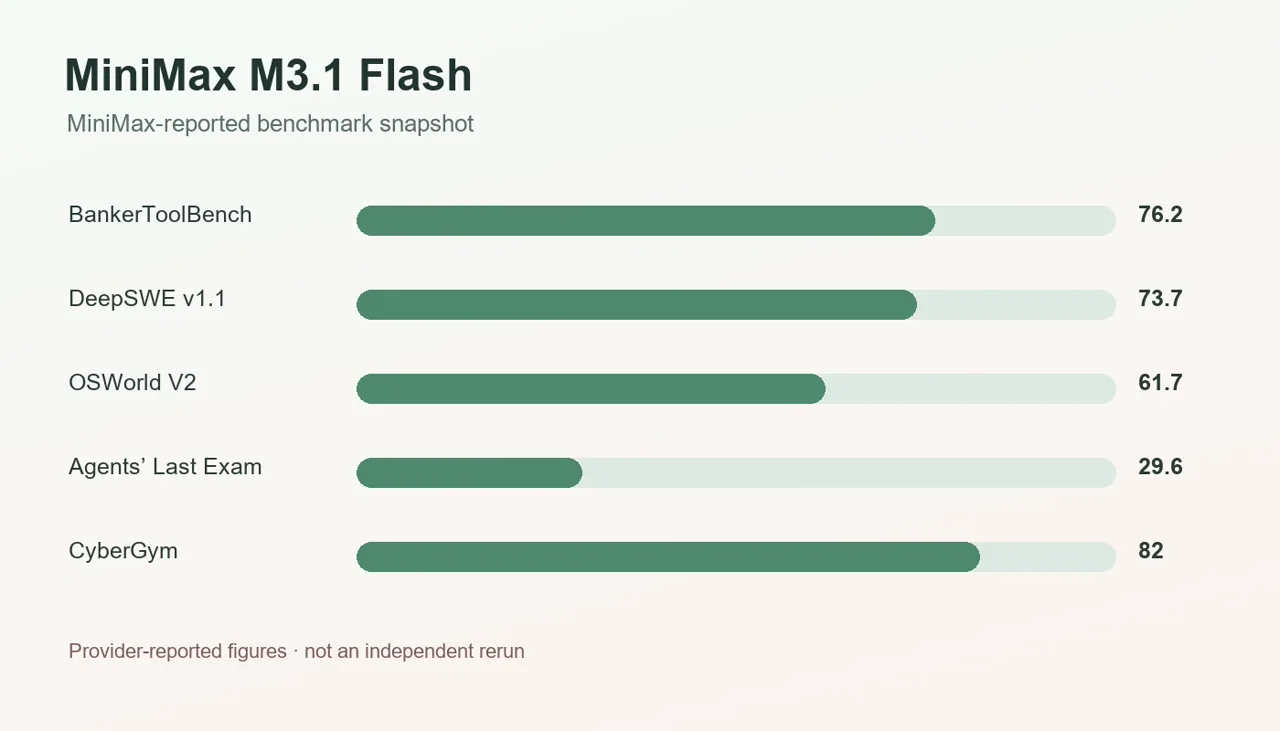
These numbers do not tell you the price of one repository fix, the latency of your region, or how well the model follows your tools. For those decisions, use a small controlled evaluation with your own prompts, tool schema, context length, and retry policy.
API pricing and cost examples
MiniMax’s pricing overview lists USD token rates for the direct API. The billing unit is one million tokens, and cached input is priced separately from uncached input. These rates describe the MiniMax API route; they are not a conversion of GlobalGPT credits or a third-party plan.
| Scénario | Calcul | Coût estimé de l'API |
|---|---|---|
| 100k input + 20k output | (0.1 × $0.15) + (0.02 × $0.60) | $0.027 |
| 100k cached input + 20k output | (0.1 × $0.015) + (0.02 × $0.60) | $0.0135 |
| 1M input + 200k output | (1 × $0.15) + (0.2 × $0.60) | $0.27 |
These are arithmetic examples before taxes, account-level discounts, retries, tool-side charges, or any platform markup. The cheapest path is usually to reuse stable prefixes as cacheable input and keep the output budget appropriate to the task instead of paying for a large completion every time.
If you are comparing direct API pricing with hosted subscriptions, keep the units separate. The Plans Claude et guide tarifaire de l'API is a useful example of why consumer plans, API tokens, and platform credits should not be treated as the same currency.
API setup: OpenAI-compatible and Anthropic-compatible
MiniMax documents two compatibility layers in its OpenAI-compatible reference et Anthropic-compatible reference. The OpenAI-compatible route is convenient if your application already uses the OpenAI SDK. The Anthropic-compatible route uses Anthropic message semantics. In both cases the documented model ID is MiniMax-M3.1-Flash; keep the spelling and capitalization exactly as shown by the target endpoint.





