Muse Wonder is worth trying for code repair and source-based analysis. The examples below passed 29 independent checks: 13 for the code-repair follow-up and eight each for source reconciliation and recovery planning. With explicit identity requirements, the returned code preserved distinct Symbols and object references while keeping the requested order and format.
メタ introduced Muse Wonder on October 12 as a frontier model for personal and professional agents. The bigger promises involve long tasks, memory and computer use. Our text tests give an early view of how it handles constraints; they do not settle those bigger claims.
You can repeat the tasks through GlobalGPT上の「Muse Wonder」 before changing your workflow. This review is published by GlobalGPT, and the platform entry is also where we ran the tests.
What is Muse Wonder?
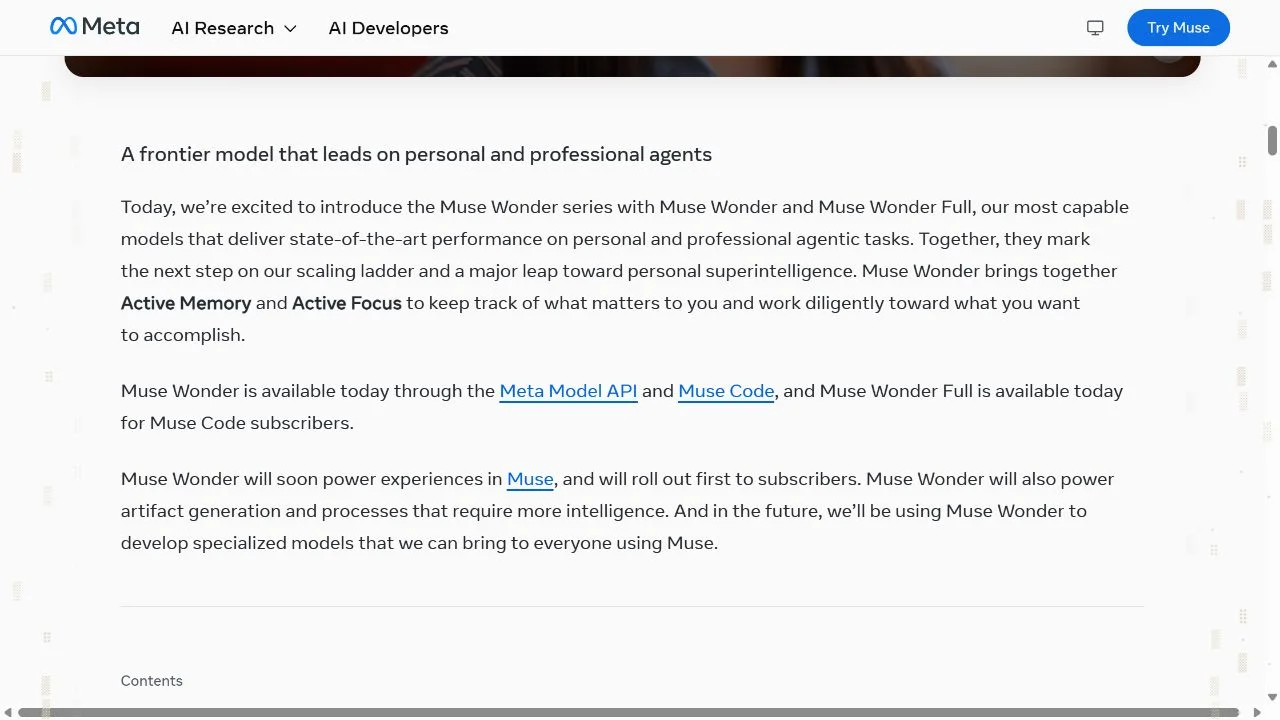
について official Meta launch announcement introduces two variants: Muse Wonder and Muse Wonder Full. It says Wonder is available through Meta Model API and Muse Code, while Full is available to Muse Code subscribers. It separately says Wonder will soon power the consumer Muse product, starting with subscribers. Those are three access surfaces with different scopes.
Metaの モデルのドキュメント identifies the standard preview model as muse-wonder-1.0. It accepts text, images, video, audio and PDFs, and returns text. Multimodal understanding can help a model explain a file or reason about a screen; it does not by itself give that model an image- or video-generation endpoint.
Choose an evaluation around what you actually need: correct code, a cited answer, a usable plan or a finished tool task. Our AIモデルの選び方ガイド helps separate those workloads before you turn a model name into a buying decision.
What Meta promises: memory, focus and context
について documented context window is 1,048,576 tokens. Meta also describes tool calling and structured outputs. A large window is useful when a task has many files, but the specification alone says little about retrieval errors, conflicting instructions or what survives a long interaction.
文脈
1,048,576Tokens documented by Meta; not stress-tested here.
インプット
マルチモーダルText, images, video, audio and PDFs.
出力
テキストPlans, analysis and code; our runs used text only.
アクセス
Two variantsStandard Wonder and Muse Code’s Wonder Full.
In Meta’s Active Memory and Active Focus launch post, Memory is about carrying relevant context across conversations; Focus is about staying with a goal when a task becomes difficult. These are attractive ideas for a working agent. Testing them needs repeated conversations and actual tool execution, not a short prompt that merely asks the model to explain the features.
That distinction shapes our test set. We tested a coding constraint, an evidence conflict and a recovery plan. The source packet fits comfortably into an ordinary chat. We did not attach images or PDFs, fill the context window, or measure persistent memory between chats.
Three real Muse Wonder tests and results
We tested three task types in GlobalGPT’s production Muse Wonder interface on October 14, 2026, using its default settings. The code example below is a follow-up with explicit identity requirements; the source and planning examples retain their original outputs. The published entry maps to agent 6256 and label ミューズ・ワンダー. No reasoning-effort control was exposed, and the provider backend version was not independently attested; these are not Wonder Full or max-effort API benchmark results.
Code basics
8 / 8Order, types, missing IDs and input preservation passed.
Evidence JSON
8 / 8Format, source choice and missing facts passed.
Recovery plan
8 / 8Six steps, 126 words and a bounded retry.
ID identity
5 / 5Symbols, references and BigInt passed in the follow-up.
Test 1: fix a real JavaScript deduplication bug
The original function used record.id || '', which collapses numeric zero, false and absent IDs into the same value. We tested stable order, case-insensitive strings, separate missing-ID records and no mutation, then followed up with explicit Symbol, object-reference and BigInt requirements. The complete prompt and returned code below are from that follow-up.
正確な入力
同じ「uniqueById」タスクに対する、コード修正後のテストを実施してください。修正済みの実行可能なJavaScript関数、簡単な説明、および正確に5つのassert形式のテストを返してください。テストを実行したとは主張しないでください。

受け入れ要件:
- 入力の順序を維持し、重複するIDごとに最初のレコードを返してください。配列やレコードを一切変更しないでください。
- id が存在しない、null または undefined であるレコードは、常に保持すること。
- 文字列 ID の比較は、大文字小文字を区別しないこと。数値の 0、ブール値の false、および文字列 '0' は区別すること。
- JavaScript の ID の同一性を保持すること:2 つの異なる Symbol('x') 値は区別されたままであり、まったく同じ Symbol が繰り返される場合は重複を排除し、繰り返される Symbol.for('shared') 値も重複を排除する必要があります。
- ID として使用される異なるオブジェクトや関数は区別されたままであり、繰り返される参照は重複を排除します。BigInt 1n と数値 1 は区別されたままです。
- 元のサンプル [{id:0},{id:false},{id:'A'},{id:'a'},{name:'one'},{name:'two'}] を使用し、0、false、最初の A、および ID を持たない両方のレコードを保持する。

提供された5つのテストは、通常のサンプル、IDの欠落・null、Symbolの同一性、オブジェクト参照の同一性、およびBigIntとnumberのケースを網羅しているはずです。異なる同一性をテキストキーに統合するのではなく、値を保持する実装を使用してください。.
自動コピーがブロックされている場合は、テキストを選択して Ctrl/Cmd+C を押してください。.モデルの出力
function uniqueById(records) {
  const seen = new Set();

  return records.filter((record) => {
    // Absent, null, and undefined IDs are always kept.
    if (record == null || record.id == null) {
      return true;
    }

    const id = record.id;

    // Normalize only strings for case-insensitive comparison.
    // All other values are stored as-is, preserving their identity.
    const key = typeof id === "string" ? id.toLowerCase() : id;

    if (seen.has(key)) {
      return false;
    }

    seen.add(key);
    return true;
  });
}
自動コピーがブロックされている場合は、テキストを選択して Ctrl/Cmd+C を押してください。.Muse Wonder lowercased only string IDs and stored other IDs directly in a セット. Records with absent, null または undefined IDs always pass through. The eight ordinary checks covered the sample, empty input, case handling, distinct types, missing IDs, immutability, order and returned-record identity. All eight passed.
モデルの出力
const assert = require("node:assert/strict");

// Test 1: Ordinary sample — string case, distinct primitive types, id-less records.
assert.deepStrictEqual(
  uniqueById([
    { id: 0 },
    { id: false },
    { id: "A" },
    { id: "a" },
    { name: "one" },
    { name: "two" },
  ]),
  [
    { id: 0 },
    { id: false },
    { id: "A" },
    { name: "one" },
    { name: "two" },
  ]
);

// Test 2: Missing, null, and undefined IDs are always kept.
assert.deepStrictEqual(
  uniqueById([
    { name: "one" },
    { id: null },
    { id: undefined },
    { name: "two" },
    { id: null },
  ]),
  [
    { name: "one" },
    { id: null },
    { id: undefined },
    { name: "two" },
    { id: null },
  ]
);

// Test 3: Symbol identity and registered symbols.
const symbolA = Symbol("x");
const symbolB = Symbol("x");
assert.deepStrictEqual(
  uniqueById([
    { id: symbolA },
    { id: symbolB },
    { id: symbolA },
    { id: Symbol.for("shared") },
    { id: Symbol.for("shared") },
  ]),
  [{ id: symbolA }, { id: symbolB }, { id: Symbol.for("shared") }]
);

// Test 4: Object and function reference identity.
const objectA = {};
const objectB = {};
function functionA() {}
function functionB() {}
assert.deepStrictEqual(
  uniqueById([
    { id: objectA },
    { id: objectB },
    { id: objectA },
    { id: functionA },
    { id: functionB },
    { id: functionA },
  ]),
  [
    { id: objectA },
    { id: objectB },
    { id: functionA },
    { id: functionB },
  ]
);

// Test 5: BigInt, number, and string IDs remain distinct.
assert.deepStrictEqual(
  uniqueById([
    { id: 1n },
    { id: 1 },
    { id: "1" },
    { id: 1n },
    { id: 1 },
    { id: "1" },
  ]),
  [{ id: 1n }, { id: 1 }, { id: "1" }]
);
We executed the model’s five assert-style tests and all passed. We also ran our own checks separately. Execution happened in our verification environment after receiving the answer; the model did not operate a repository or independently attest a test run.
Five additional identity checks passed: distinct same-description Symbols remain separate; repeated identical Symbols deduplicate; registered Symbols deduplicate; objects and functions preserve reference identity; and 1n remains distinct from 1. That makes 13 independent checks for this follow-up version, in addition to the five model-supplied assertions.
If code quality is your main reason to switch, use the コーディング比較に最適なAIモデル to choose a second model and run the same input. We did not run a matched competitor test here, so this result does not establish a ranking.
Test 2: reconcile conflicting evidence into valid JSON
The second task used a fictional Orion Agent packet. An older announcement said $19/month and EU availability; newer official sources said $24/month and a paused EU rollout. An unsupported community claim said $12. The missing output price and restart date were deliberate traps for invented certainty. None of these fictional prices are Muse Wonder pricing.
正確な入力
Muse Wonder レビューテスト 2:証拠の照合。
この架空のソースパケットのみを使用してください。keyとして launch_date、plan_monthly_usd、api_input_per_million_usd、region_status、unresolved、citations を含む有効な JSON のみを返してください。各事実値には、citations にそのソース ID が含まれている必要があります。 矛盾する情報を黙って平均化したり、欠落している事実をでっち上げたりしてはなりません。

[S1] 製品発表(2026年10月12日付):Orion Agentは10月12日にリリースされました。Proプランは月額$19です。米国およびEUで利用可能です。
[S2] 公式価格ページ(2026年10月14日更新):Proプランは$24/月、月次課金。API入力は100万トークンあたり$4。API出力は記載なし。
[S3] 公式ステータスページ(2026年10月14日更新):米国でのアクセスは稼働中。EUでの展開は一時停止中。再開日は未定。
[S4] コミュニティ投稿(2026年10月14日):あるユーザーによると、プランは$12で、EUでも利用可能とのこと。スクリーンショットやリンクはなし。

同じ項目については、より新しい公式情報を使用することを推奨します。未解決の情報がある場合は、明示的に記載してください。.
自動コピーがブロックされている場合は、テキストを選択して Ctrl/Cmd+C を押してください。.
モデルの出力
{"launch_date": "2026-10-12", "plan_monthly_usd": 24, "api_input_per_million_usd": 4, "region_status": {"US": "稼働中", "EU": "停止中"}, "unresolved": ["APIの出力価格が情報源に記載されていない。", "EUでの展開再開日が指定されていない。", "矛盾する主張は、選択された値の根拠として使用されませんでした:S1ではProプランが$19/月、EUが利用可能と記載されていたのに対し、非公式かつサポート対象外のS4では$12/月とされ、EUが機能すると主張していました; その代わりに、より新しい公式情報であるS2およびS3が優先された。", "引用元": {"リリース日": ["S1"], "プラン月額(USD)": ["S2"], "api_input_per_million_usd": ["S2"], "region_status": ["S3"]}}The output parsed as JSON and contained the six requested keys. It chose 24 from S2, chose “paused” from S3, retained S1 for the launch date and kept the missing output price and EU restart date unresolved. It did not cite S4 as the basis for a selected fact. All eight checks passed.
This is the most useful result for everyday research work: the model preferred newer official evidence for the same field without erasing what it still could not know. It is a small source-reconciliation test, not a web-search accuracy score or a million-token retrieval result.
Use a redacted packet when reproducing the task with business material. Our AIデータプライバシーガイド covers questions to ask about the platform and provider; accurate source handling alone does not establish privacy terms.
Test 3: plan recovery after an official page fails
The third prompt simulated a browser agent facing HTTP 500, conflicting price claims and no authorized API key. It asked for exactly six steps, no more than 140 words and a concrete stopping condition. It explicitly requested planning rather than real tool execution.
正確な入力
Muse Wonder レビューテスト 3:復旧計画(実際のツール実行ではない)。
ブラウザエージェントは、公開されている製品価格を収集し、比較案を作成しなければならない。公式の価格ページからは HTTP 500 が返される。あるマーケットプレイスでは、入力として $4/M、出力として $20/M が表示されている。 Redditの検索スニペットには「$1/M」と記載されている。ユーザーは証拠となるスクリーンショットと実機での実行結果を望んでいる。認証済みのAPIキーは利用できない。
番号付きのステップを正確に6つ記述し、総文字数は140語以内とする。 再試行の回数に上限を設け、失敗したページの記録を保持し、マーケットプレイスの価格情報を明記し、Redditのスニペットを検証済みとして扱わず、準備段階とモデルテストの完了を明確に区別してください。ログインを省略したり、スクリーンショットや出力を捏造したりしないでください。手順6の最後には、具体的な終了条件を明記してください。.
自動コピーがブロックされている場合は、テキストを選択して Ctrl/Cmd+C を押してください。.
モデルの出力
1. 公式価格ページへのアクセスを、短い間隔を空けて最大3回まで再試行する。タイムスタンプ、URL、HTTP 500ステータス、および実際のエラーページのスクリーンショットを、失敗記録として保存する。
2. マーケットプレイスの掲載情報を「マーケットプレイス由来の価格」として記録する:入力値「$4/M」、出力値「$20/M」とし、出典URLおよび日付を明記する。公式価格として提示してはならない。
3. Redditのスニペットで主張されている「$1/M」については、未確認の情報としてのみ記録する。公式または信頼できる情報源によって裏付けられるまでは、検証済みの比較対象から除外する。
4. 検証済み、帰属済み、未確認のエントリを区分した比較表の草案を作成し、公式な確認が得られていない旨を明記する。
5. モデルテスト計画、プロンプト、および採点シートを準備する(実行はしない)。承認されたAPIキーがない場合は、ログインを省略したり、スクリーンショットや出力を偽造したりしてはならない。ステータスを「未テスト」と明記する。
6. 草案は準備段階のものとして報告し、完了したモデルテストとして扱わない。3回の再試行に失敗し、合意された期限までに承認されたキーが届かない場合は、作業を中止する。.
Muse Wonder produced six steps totaling 126 words, excluding step numbers. It bounded retries at three, retained the failed-page evidence, attributed marketplace prices, treated the Reddit snippet as unverified and kept preparation separate from a completed model test. All eight checks passed.
The plan’s final deadline was not given a timestamp, so a real operator would still have to set it. More fundamentally, a good plan does not prove the agent can execute clicks, recover a tool connection or finish a long workflow. That is also why our AIアシスタントの比較ランキング(実証済み) distinguishes different assistant tasks rather than treating every fluent answer as automation.
What these runs did not measure
These examples cover three task types with no competing model. Code repair includes an explicit-requirements follow-up. The selected code, JSON and plan displayed “Took 18s,” “Took 10s” and “Took 11s”; those are platform labels, not independent latency measurements. We did not audit task-specific credit debits, provider token usage, persistent Active Memory, long context, multimodal files or live computer use.
The complete code, JSON and planning text is retained in the panels above. Use the exact inputs and verify the returned text when reproducing these examples; the accepted code is the follow-up version, and its result does not imply universal correctness for every application.
X benchmarks and Reddit reactions
について AI at Meta launch thread on X frames Wonder and Full around personal and professional agent work. That is the model maker’s intended positioning. Our tests support some basic instruction-following observations, while the memory and execution claims remain separate.
その 当初のX評価, Artificial Analysis reports Intelligence Index v4.3 scores of 52 for Muse Wonder and 56 for Wonder Full at maximum reasoning effort, versus 48 for Muse Spark 1.3. The organization also distinguishes standard API access from Full in Muse Code. We read the original report; we did not reproduce its evaluations.
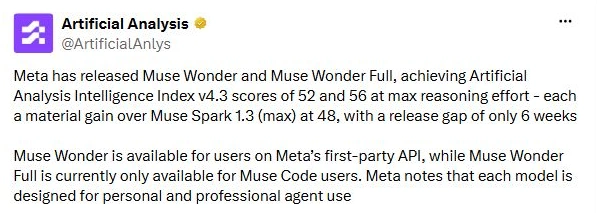
Reported scores · maximum reasoning effort · not our benchmark
Bars use a display range of 0–60, not a percentage scale. Source: Artificial Analysis original post.
The same report is positive about gains in agent tasks, but flags premium standard-model pricing and knowledge as a relative weakness. That combination is more informative than “new frontier model”: a model can improve at agent work while still being the wrong economic choice for a frequent task. Its reported benchmark cost per task should not be reused as the price of our chat runs.
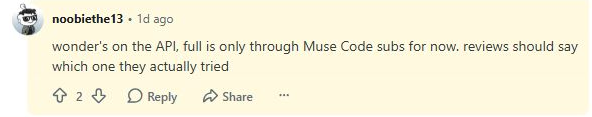
On Reddit, the original LocalLLaMA post has been removed by moderators, but comments remain readable. u/noobiethe13 は次のように書きました: “wonder’s on the API, full is only through Muse Code subs for now. reviews should say which one they actually tried”. The practical point matches Meta’s access distinction: an unspecified “Wonder review” can mix two different routes.
Another commenter, u/ComplexType568, wrote: “Hope they release a new open weights model and also an MoE model…” That is an openness preference, not a measured quality result.
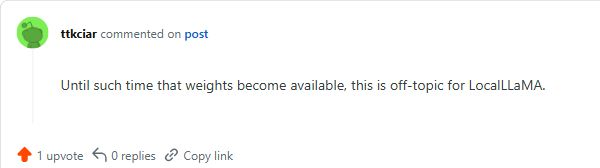
Moderator u/ttkciar explained the removal: “Until such time that weights become available, this is off-topic for LocalLLaMA.” These comments were posted October 13 and read on October 14. They explain this thread’s concerns; they do not establish a Reddit-wide consensus or a reliability score.
Muse Wonder pricing: tokens versus subscriptions
について OpenRouter Muse Wonder の商品ページ checked October 14 quotes $4 per million input tokens, $0.20 per million cached input tokens and $20 per million output tokens. These are marketplace-listed API rates, attributed to OpenRouter rather than presented as a verified Meta invoice or checkout total.
API input
$4 / MOpenRouter listing; uncached input tokens.
キャッシュされた入力
$0.20 / MListing rate; eligibility for caching matters.
API output
$20 / MListing rate; separate from subscription fees.
At those listed rates, an illustrative request with 10,000 uncached input tokens and 2,000 output tokens would cost $0.08: (10,000 ÷ 1,000,000 × $4) + (2,000 ÷ 1,000,000 × $20). This is arithmetic from displayed rates, excluding any other applicable charges. It is not the audited price of a completed review task.
Muse Code subscription access, standard API token billing and GlobalGPT credits are different units. Full’s Muse Code access does not establish a per-token price for Full, and setting standard Wonder to high reasoning effort does not select Full. We did not verify a current Muse Code checkout total or a per-task GlobalGPT debit.
If you run the same workflow daily, compare accepted output and retry cost as well as the headline rate. Our どのAIにお金を払う価値があるのか is useful for that broader subscription decision; a cheaper token rate can still be poor value if the task needs more attempts.
How to use Muse Wonder on GlobalGPT
について Muse Wonder production entry on GlobalGPT was published and enabled when checked. The original tasks and the code-repair follow-up completed there. Open it, confirm the Muse Wonder label and paste a complete prompt above. Judge the response against the stated checks before applying it to your own files.
For code repair, spell out the allowed ID types and the expected equality rules. Start with a small sample, then check case handling, missing values, identity and input preservation. A specific acceptance list makes the returned function easier to verify and adapt.
For direct API work, Meta’s Model API overview 文書 https://api.meta.ai/v1, the standard model ID and a bearer key requirement. Our browser runs used the existing platform access; they do not establish that an arbitrary Meta API key or another gateway can call the same backend.
GlobalGPT is convenient when you want to repeat a prompt and compare other models in one workspace. The オールインワンAIモデルのワークフロー describes that workflow. It does not make the chat interface equivalent to Muse Code’s terminal agent or guarantee that every native memory/tool feature is exposed.
Who should use it? Our verdict
Try Muse Wonder for bounded coding, evidence cleanup and planning tasks. Our code run met the ordinary-ID requirements, the source run retained uncertainties and the planning run obeyed the recovery constraints. Those are concrete reasons to try it with a task you can verify.
Good first task
Code repairA small function with explicit accepted inputs and checks.
Useful research task
Source cleanupDated evidence, named sources and required unresolved fields.
Needs a deeper test
Agent executionMemory, browser recovery and long workflows remain untested.
Keep human review for production changes and define the accepted inputs before using generated code. Our follow-up checks support this specific implementation. If you need Wonder Full, evaluate the actual Muse Code route. For persistent memory or live computer use, run a separate end-to-end task and save its tool trace.
For audio workflows, do not infer speech-generation quality from these text runs. A AI voice agents for customer support workflow also needs speech recognition, a voice output route and its own latency checks; Wonder’s documented audio input alone does not prove the whole stack.
Our early verdict is positive but specific: Muse Wonder handled the tested tasks well enough to earn a place in a practical trial. The next meaningful step is your own verified task, not a universal “best model” claim from these examples.
Muse Wonder review FAQ
What is Muse Wonder?
Muse Wonder is Meta’s frontier agent model, launched October 12, 2026. Meta documents text, image, video, audio and PDF inputs, text output, and a 1,048,576-token context window.
Is Muse Wonder good for coding?
The code-repair follow-up passed 13 independent checks, including Symbol identity, object references, BigInt, order and input preservation. We made the identity requirements explicit and also executed all five supplied assertions successfully.
Did this review actually test Muse Wonder?
Yes. We tested code repair, conflicting-source JSON and recovery planning in GlobalGPT’s production interface. The examples shown passed 29 independent checks. The code example is a follow-up with explicit identity requirements.
Can I use Muse Wonder on GlobalGPT?
Yes. We verified the published Muse Wonder entry and completed the original tasks and a code-repair follow-up there on October 14, 2026. The interface labels the model Muse Wonder; its exact provider backend version was not independently attested.
What is the difference between Muse Wonder and Wonder Full?
Meta offers standard Wonder through Model API and Muse Code. The launch announcement limits Wonder Full to Muse Code subscribers. Our GlobalGPT runs do not establish that we tested Full.
How much does Muse Wonder cost?
The OpenRouter listing checked October 14, 2026 quotes $4/M input, $0.20/M cached input and $20/M output tokens. Those marketplace rates are separate from Muse Code subscriptions and GlobalGPT credits.
Does Muse Wonder generate images or video?
Meta’s model documentation specifies multimodal inputs and text output. Understanding an image or video is different from generating one; this review tested text tasks only.
Did the tests prove Active Memory or computer use?
No. The source packet was short, and the recovery task requested a plan only. We did not test cross-chat memory, a million-token input, multimodal files or live computer-use execution.